<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="http://www.independent-software.com/feed.xml" rel="self" type="application/atom+xml" /><link href="http://www.independent-software.com/" rel="alternate" type="text/html" /><updated>2026-08-12T17:07:51+00:00</updated><id>http://www.independent-software.com/feed.xml</id><title type="html">Independent Software</title><subtitle>Independent Software crafts beautiful, professional websites and database solutions.</subtitle><author><name>Alexander van Oostenrijk</name></author><entry><title type="html">Operating System Development: Interrupts</title><link href="http://www.independent-software.com/operating-system-development-interrupts.html" rel="alternate" type="text/html" title="Operating System Development: Interrupts" /><published>2026-08-12T11:49:00+00:00</published><updated>2026-08-12T11:49:00+00:00</updated><id>http://www.independent-software.com/operating-system-development-interrupts</id><content type="html" xml:base="http://www.independent-software.com/operating-system-development-interrupts.html"><![CDATA[<p>Before we move on with our kernel development, we must talk about an important
concept in operating systems: <em>interrupts</em>. When the CPU executes a program in
memory, it will take an instruction, execute it, take the next instruction,
execute that, and continues without ever stopping. It isn’t distracted by
anything that happens in the wider world.</p>

<p>Sometimes, though, it’s necessary to tell the CPU to stop executing a program, 
just for a moment, and direct its attention elsewhere. Perhaps some piece of 
hardware needs servicing: a user pressed a button on the keyboard or moved the 
mouse; a network request has completed; a disk read operation failed. It’s 
also possible that we want the CPU to execute more than one program at a 
time, switching between them every few microseconds. To do that, we set
an alarm clock that rings, interrupting the CPU from its work.</p>

<p>In this section, we’ll look at what interrupts are.</p>

<p><em>This article is part of a <strong>series on toy operating system development.</strong></em></p>

<p><a href="/operating-system-development.html" class="btn">View the series index</a></p>

<!--more-->

<h2 id="the-dedicated-cpu">The dedicated CPU</h2>

<p>Once you power on the CPU, it is a machine of sheer single mindedness. It 
operates in a simple loop: read instruction from memory, decode instruction,
execute instruction, move pointer to next bit of memory, repeat. It never
stops doing this; you’ll have to pull the plug to get it to stop - or feed
it an instruction it doesn’t know what to do with. Short of these, nothing
will distract it from its work.</p>

<p>Sometimes, though, the world around the CPU needs its attention.</p>

<ul>
  <li>The CPU is surrounded by hardware that it has no knowledge about. The CPU
doesn’t know what a keyboard is, or a mouse, or a disk drive. When you press
a key on the keyboard, then this has no meaning for the CPU; it continues
executing instructions. What’s needed is for the CPU to notice that something
in its environment happened, and needs attention.</li>
  <li>Operating systems execute multiple processes at the same time. They do
this by having the CPU execute some instructions from process A, then stop it,
and set it work on process B. The CPU is moved from process to process every
few microseconds - a concept known as <strong>scheduling</strong>. What’s needed is a way
to set an alarm clock; when it rings, the CPU has to move to the next process.
The process switching happens so frequently that to the user it appears that
the CPU is executing all processes simultaneously.</li>
  <li>It’s possible for the CPU to encounter an error. It may, for example,
try to divide by zero. That’s not the CPU’s fault; it is the program that it’s
executing that made it attempt the division. Dividing by zero is impossible,
and sends the CPU screaming. But who does it scream to? Itself, actually: 
it needs a way to stop attempting to divide and execute some other code
that allows it to recover from the error.</li>
</ul>

<h2 id="interrupting-the-cpu">Interrupting the CPU</h2>

<p>The way to get the CPU’s attention is by <strong>interrupting</strong> it. When something
of note happens to a piece of hardware, that hardware talks to a special
chip known as the <em>Programmable Interrupt Controller</em> (PIC), sending
it an <em>Interrupt Request</em> (IRQ). The PIC then communicates this request to
the CPU. Receiving this <em>interrupt</em>, the CPU then stops doing what is was 
doing, acknowledges receipt to the PIC which in turns sends a vector (a number: one 
value for the keyboard, another value for the mouse, and so on). The CPU 
then executes a special bit of code to <em>service the interrupt</em>, appropriately 
known as an <strong>interrupt service routine</strong>. 
When it’s done, the CPU goes back to what it was doing before it was interrupted.</p>

<p><img src="http://www.independent-software.com/assets/osdev/programmable-interrupt-controller.webp" alt="Programmable Interrupt Controller" /></p>

<div style="text-align: center">
  <p><em>This Intel 8259 Programmable Interrupt Controller can be yours for $10.95</em></p>
</div>

<blockquote>
  <p>Note: in modern computers the 8259 PIC has given way to the
APIC (“Advanced”): a local APIC on each CPU core, plus one or more I/O
APICs for the devices. PCIe devices go further still, posting their interrupts
as writes to memory (while PICs use a controller pin). For the theory in 
this post, none of this makes any difference.</p>
</blockquote>

<p>The second use case - an alarm clock that interrupts the CPU so that it can
tend to the next process that’s scheduled - works in a similar way. The kernel
programs a special chip to fire off an interrupt every few microseconds,
the CPU gets interrupted, and the interrupt service routine is written to
call the kernel again, which will move some registers around so that the CPU
will start executing the next process.</p>

<p>There are a number of errors that can happen during program execution: 
divide-by-zero is the typical example, but other things include an invalid
opcode that the CPU doesn’t know what to do with, a stack overflow, or reading
or writing to a region of memory where a process isn’t allowed. These will need
dealing with by an operating system kernel: retry, or halt the offending 
process. On this occasion it is the CPU that fires off an interrupt, 
interrupting <em>itself</em>, so that an interrupt service routine (installed by 
the kernel) can run in order to put things right.</p>

<p>There’s a fourth use case still: a user program needing to talk to the
kernel, in order to request a service (a <em>software interrupt</em>). The kernel 
knows how to speak to hardware on the program’s behalf, for example, and it 
can execute code at a higher privilege level than the user program. 
In previous chapters, we’ve already used the <code class="language-plaintext highlighter-rouge">INT</code> assembly instruction to 
call the BIOS. We’ve asked it to print a character to the screen, wait for a 
keypress, and produce a memory map. The difference is that we’ve moved to 
protected mode, and talking to the BIOS is out the window - we’ll have to 
provide all of these services ourselves, but more on that later.</p>

<h2 id="the-interrupt-service-routine">The interrupt service routine</h2>

<p>Whenever the CPU gets interrupted, then, it will execute an interrupt service
routine. As we’ve seen, this can be the result of:</p>

<ul>
  <li>Hardware interruption of the CPU (this includes the scheduling alarm clock)</li>
  <li>A program execution error</li>
  <li>A program executing the <code class="language-plaintext highlighter-rouge">INT</code> instruction</li>
</ul>

<p>Each interrupt has a number. That number is an index into a table sitting
somewhere in memory. The table is known as an <strong>interrupt vector table</strong>: for
each interrupt, it contains the memory address of its interrupt service
routine.</p>

<blockquote>
  <p>Note: the shape of the interrupt vector table has changed over the years, 
but the idea behind it hasn’t. A real-mode CPU has 256 entries of four bytes 
each, sitting at address 0x0, and each one is just a segment + offset. 
A protected-mode CPU has 256 <em>gate descriptors</em> instead, each containing more
than just an address. Additionally, the modern table can live anywhere in memory,
and we use <code class="language-plaintext highlighter-rouge">LIDT</code> to tell the CPU where (which we’ve done before).</p>
</blockquote>

<p>The interrupt service routine is a piece of code which can do whatever it wants,
subject to two constraints.</p>

<ul>
  <li>
    <p>The routine must leave the machine exactly
as it found it: every register it touches has to be saved and put back, because
the interrupted program doesn’t kow ut was interrupted and will carry on
using those registers as though nothing had happened.</p>
  </li>
  <li>
    <p>An interrupt arrives between two arbitrary instructions, so an ISR may well 
have interrupted code that was halfway through updating a data structure. It 
cannot assume that anything it looks at is in a consistent state, and it must 
never wait for a lock that the interrupted code might already be holding - 
that code is not running, and will not release the lock until the ISR returns. 
A routine which can safely be entered while an earlier invocation of it is 
still in progress is called <strong>reentrant</strong>.</p>
  </li>
</ul>

<p>An ISR is special in one other way: while an ordinary subroutine
returns with <code class="language-plaintext highlighter-rouge">RET</code>, an ISR uses <code class="language-plaintext highlighter-rouge">IRET</code>. This is because the CPU, when it gets
interrupted, leaves a return address on the stack automatically <em>and</em> pushes
the flags; <code class="language-plaintext highlighter-rouge">IRET</code> pops them off again. This is important because the interrupted
program’s carry and zero flags have to survive, as does the interrupt-enable state.</p>

<p>The return address is a little bit special, and is different for three kinds of
interrupts:</p>

<ul>
  <li>For a <strong>fault</strong>, the saved address points <em>at</em> the offending instruction, so
that it can be retried once the condition has been fixed. A page fault is the
standard example: map the missing page, <code class="language-plaintext highlighter-rouge">IRET</code>, and the instruction now
succeeds.</li>
  <li>For a <strong>trap</strong>, the saved address points <em>after</em> the instruction. Breakpoints,
overflow, and the software <code class="language-plaintext highlighter-rouge">INT</code> instruction all behave this way.</li>
  <li>For an <strong>abort</strong>, there is no reliable address at all. A double fault is an
abort: there is nothing sensible left to return to.</li>
</ul>

<p>The barest (and not useful) implementation for interrupts is therefore a
table of pointers, all the same, and at that pointer lives the <code class="language-plaintext highlighter-rouge">IRET</code>
instruction. Or <code class="language-plaintext highlighter-rouge">HLT</code>, in case of an error.</p>

<blockquote>
  <p>Note: some of the error interrupts push an extra word onto the stack describing
what went wrong, so this word must be removed before <code class="language-plaintext highlighter-rouge">IRET</code> can return to
the correct place.</p>
</blockquote>

<h2 id="interrupt-masking">Interrupt masking</h2>

<p>There’s a detail worth mentioning at this point: the CPU has special instructions
allowing it to ignore interrupts. This is known as <em>interrupt masking</em>, and it’s
the equivalent of the CPU inserting a finger in each ear and going “LA-LA-LA”
until the masking is turned off.
The <code class="language-plaintext highlighter-rouge">CLI</code> instruction turns off interrupts, and <code class="language-plaintext highlighter-rouge">STI</code> turns them back on again; 
instructions we have already used in the boot loader.</p>

<p>Interrupts are also masked automatically while an interrupt service routine is
running, otherwise an interrupt could interrupt an interrupt and most of the 
time, we won’t have that. In protected mode this turns out to be a property 
of the table entry rather than of interrupts in general: an entry can be 
marked either to mask interrupts on the way in or to leave them alone.</p>

<p>Not everything can be masked, though. Some events are too serious to be ignored
at the CPU’s convenience (imminent power loss, or a memory parity error) and
these arrive as a <strong>non-maskable interrupt</strong>, which <code class="language-plaintext highlighter-rouge">CLI</code> cannot switch off. 
When one of those turns up, something is wrong with the machine rather than 
with the program it’s running.</p>

<h2 id="summary">Summary</h2>

<p>In this article, we’ve explored what <strong>interrupts</strong> are: a way for either
software, hardware, or a program error to make the CPU stop executing program 
code and jump to an interrupt service routine, returning to its original job
when it’s done.  When we first enter protected mode, there aren’t any
interrupt service routines yet, so the CPU has no idea what to do when
an interrupt is fired. In the next article, we’ll see how to set up
an interrupt vector table.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="osdev" /><category term="asm" /><summary type="html"><![CDATA[Before we move on with our kernel development, we must talk about an important concept in operating systems: interrupts. When the CPU executes a program in memory, it will take an instruction, execute it, take the next instruction, execute that, and continues without ever stopping. It isn’t distracted by anything that happens in the wider world. Sometimes, though, it’s necessary to tell the CPU to stop executing a program, just for a moment, and direct its attention elsewhere. Perhaps some piece of hardware needs servicing: a user pressed a button on the keyboard or moved the mouse; a network request has completed; a disk read operation failed. It’s also possible that we want the CPU to execute more than one program at a time, switching between them every few microseconds. To do that, we set an alarm clock that rings, interrupting the CPU from its work. In this section, we’ll look at what interrupts are. This article is part of a series on toy operating system development. View the series index]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/monolith.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/monolith.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Operating System Development: Memory Map</title><link href="http://www.independent-software.com/operating-system-development-memory-map.html" rel="alternate" type="text/html" title="Operating System Development: Memory Map" /><published>2026-08-10T14:30:00+00:00</published><updated>2026-08-10T14:30:00+00:00</updated><id>http://www.independent-software.com/operating-system-development-memory-map</id><content type="html" xml:base="http://www.independent-software.com/operating-system-development-memory-map.html"><![CDATA[<p>It has been a while since there we any updates to this, the in-depth guide
to <strong>toy operating system development</strong>! But oh well, what’s thirteen years
between friends? When last we were here, we had built first and second-stage
boot loaders, and a kernel that said “Hello world”, then hung. It’s high
time to move on.</p>

<p>In this section, we’ll be looking at the system’s memory map. As we’ll soon
need to write memory management (to be done by our brand new kernel), we’ll
need to know which areas of memory we can touch, and which are off-limits. 
Overwriting the kernel itself, for example, would be bad, and overwriting 
the global interrupt table would bring the system down, as well.</p>

<p><em>This article is part of a <strong>series on toy operating system development.</strong></em></p>

<p><a href="/operating-system-development.html" class="btn">View the series index</a></p>

<!--more-->

<h2 id="memory-map">Memory map</h2>

<p>After we hit protected mode, all memory of the system becomes available to our
kernel: vast fields of bytes, ready to be written, read, shifted, or fondled
in other ways. But not all memory is equal! Some memory can’t be written
to (ROM), and it’d be bad if we tried. Other memory is directly mapped to
devices: the VGA card, for example, is tied to a specific area of memory. 
But there’s more: our kernel doesn’t even know how <em>much</em> memory our system has. 
It literally can’t see the end of those vast fields of bytes.</p>

<p>Which areas of memory are actually not available to us is something that 
varies from machine to machine. A different graphics card would use a different
area of memory (CGA cards where at 0xB800, VGA at 0xA000). Our kernel
doesn’t know these things - but the BIOS knows. The BIOS has a special interrupt
that gets us a nice memory map: a list of sections, each marked as usable
or reserved.</p>

<p>There’s but one catch: this is a <em>BIOS</em> interrupt, so it has to be called
from real mode. This means we must call it before we ever go into protected mode,
and so the code that we write in this article must be inserted into our
second-stage bootloader. While that’s not a problem, we must also find a way
to pass the memory map we obtain to the kernel, which will make use of it. This
means we must place the map somewhere in memory - temporarily - and let
the kernel find it there.</p>

<h2 id="the-interrupt">The interrupt</h2>

<p>The interrupt that’ll get us our memory map is <code class="language-plaintext highlighter-rouge">int 0x15</code>, subfunction <code class="language-plaintext highlighter-rouge">0xe820</code>. 
It’s documented <a href="http://www.uruk.org/orig-grub/mem64mb.html">here</a>
and <a href="https://wiki.osdev.org/Detecting_Memory_(x86)">here</a></p>

<p>The input is:</p>

<div class="table">
  <table rules="groups">
    <thead>
      <tr>
        <th style="text-align: left">Register</th>
        <th style="text-align: left">Meaning</th>
        <th style="text-align: left">Description</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">eax</code></td>
        <td style="text-align: left">function code</td>
        <td style="text-align: left">0xe820</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">ebx</code></td>
        <td style="text-align: left">continuation</td>
        <td style="text-align: left">Contains the “continuation value” to get the next run of physical memory.  This is the value returned by a previous call to this routine.  If this is the first call, <code class="language-plaintext highlighter-rouge">ebx</code> must contain zero.</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">es:di</code></td>
        <td style="text-align: left">buffer pointer</td>
        <td style="text-align: left">Pointer to an  <em>Address Range Descriptor</em> structure  which the BIOS is to fill in.</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">ecx</code></td>
        <td style="text-align: left">buffer size</td>
        <td style="text-align: left">The length in bytes of the structure passed to the BIOS. The BIOS will fill in at most <code class="language-plaintext highlighter-rouge">ecx</code> bytes of the structure or however much of the structure the BIOS implements. The minimum size which must be supported by both the BIOS and the caller is 20 bytes.  Future implementations may extend this structure.</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">edx</code></td>
        <td style="text-align: left">signature</td>
        <td style="text-align: left">‘SMAP’ - Used by the BIOS to verify the caller is requesting the system map information to be returned in <code class="language-plaintext highlighter-rouge">es:di</code>.</td>
      </tr>
    </tbody>
  </table>
</div>

<p>And the call will return:</p>

<div class="table">
  <table rules="groups">
    <thead>
      <tr>
        <th style="text-align: left">Register</th>
        <th style="text-align: left">Meaning</th>
        <th style="text-align: left">Description</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">cf</code></td>
        <td style="text-align: left">carry flag</td>
        <td style="text-align: left">Non-Carry - indicates no error</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">eax</code></td>
        <td style="text-align: left">signature</td>
        <td style="text-align: left">Signature to verify correct BIOS revision</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">es:di</code></td>
        <td style="text-align: left">buffer pointer</td>
        <td style="text-align: left">Returned Address Range Descriptor pointer. Same value as on input.</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">ecx</code></td>
        <td style="text-align: left">buffer size</td>
        <td style="text-align: left">Number of bytes returned by the BIOS in the address range descriptor.  The minimum size structure returned by the BIOS is 20 bytes.</td>
      </tr>
      <tr>
        <td style="text-align: left"><code class="language-plaintext highlighter-rouge">ebx</code></td>
        <td style="text-align: left">continuation</td>
        <td style="text-align: left">Contains the continuation value to get the next address descriptor.  The actual significance of the continuation value is up to the discretion of the BIOS.  The caller must pass the continuation value unchanged as input to the next iteration of the E820 call in order to get the next <em>Address Range Descriptor</em>.  A return value of zero means that this is the last descriptor.  Note that the BIOS indicate that the last valid descriptor has been returned by either returning a zero as the continuation value, or by returning carry.</td>
      </tr>
    </tbody>
  </table>
</div>

<p>The <em>Address Range Descriptior</em> that the BIOS will place at <code class="language-plaintext highlighter-rouge">es:di</code> looks like this:</p>

<div class="table">
  <table rules="groups">
    <thead>
      <tr>
        <th style="text-align: left">Offset</th>
        <th style="text-align: left">Name</th>
        <th style="text-align: left">Description</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: left">0</td>
        <td style="text-align: left">BaseAddrLow</td>
        <td style="text-align: left">Low 32 Bits of Base Address</td>
      </tr>
      <tr>
        <td style="text-align: left">4</td>
        <td style="text-align: left">BaseAddrHigh</td>
        <td style="text-align: left">High 32 Bits of Base Address</td>
      </tr>
      <tr>
        <td style="text-align: left">8</td>
        <td style="text-align: left">LengthLow</td>
        <td style="text-align: left">Low 32 Bits of Length in bytes</td>
      </tr>
      <tr>
        <td style="text-align: left">12</td>
        <td style="text-align: left">LengthHigh</td>
        <td style="text-align: left">High 32 Bits of Length in bytes</td>
      </tr>
      <tr>
        <td style="text-align: left">16</td>
        <td style="text-align: left">Type</td>
        <td style="text-align: left">Address type of this range.</td>
      </tr>
    </tbody>
  </table>
</div>

<p>… where “type” can be one of:</p>

<div class="table">
  <table rules="groups">
    <thead>
      <tr>
        <th style="text-align: left">Type</th>
        <th style="text-align: left">Description</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: left">1</td>
        <td style="text-align: left">Available memory: this run is available RAM usable by the	operating system.</td>
      </tr>
      <tr>
        <td style="text-align: left">2</td>
        <td style="text-align: left">Reserved memory: This run of addresses is in use or reserved by the system, and must not be used by the operating system.</td>
      </tr>
      <tr>
        <td style="text-align: left">3</td>
        <td style="text-align: left">ACPI reclaimable</td>
      </tr>
      <tr>
        <td style="text-align: left">4</td>
        <td style="text-align: left">ACPI NVS - must survive sleep states</td>
      </tr>
      <tr>
        <td style="text-align: left">5</td>
        <td style="text-align: left">Bad memory - firmware knows it is faulty</td>
      </tr>
      <tr>
        <td style="text-align: left">other</td>
        <td style="text-align: left">Reserved for future use.  Any range of this type must be treated by the OS as if the type returned were reserved.</td>
      </tr>
    </tbody>
  </table>
</div>

<p>A “reserved” area of memory could be ROM, RAM in use by ROM, or memory mapped to
a system device.</p>

<h2 id="acpi-30">ACPI 3.0</h2>

<p>In 2004, the Advanced Configuration and Power Interface specification (ACPI)
added (among other things) a change to the memory map interrupt: rather than
returning 20 bytes, it would now return 24 bytes. The last 32 bits have the
following meaning:</p>

<div class="table">
  <table rules="groups">
    <thead>
      <tr>
        <th style="text-align: left">Bit</th>
        <th style="text-align: left">Meaning</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: left">0</td>
        <td style="text-align: left">Enabled. If clear, ignore this entry entirely, whatever its type says</td>
      </tr>
      <tr>
        <td style="text-align: left">1</td>
        <td style="text-align: left">Non-Volatile. The range keeps its contents across a power cycle - battery-backed or NVDIMM-style, not ordinary DRAM</td>
      </tr>
    </tbody>
  </table>
</div>

<p>A proper kernel will have to take these ACPI improvements into account, but
also deal with older BIOSes that <em>don’t</em> carry them. More ifs and thens, therefore.</p>

<h2 id="getting-the-map---a-recipe">Getting the map - a recipe</h2>

<p>Right, so there’s one interrupt, which we need to call repeatedly, until the
return value indicates that there are no more ~lands to conquer~ memory runs
to be found. We also need to take a potential ACPI extension into account. 
Note that the <a href="https://wiki.osdev.org/Detecting_Memory_(x86)">OSDev wiki’s page for memory detection</a> discusses still other interrupts that might be used to detect memory, but
interrupt <code class="language-plaintext highlighter-rouge">0x15/E820</code> is 99% of the process - since we’re not currently trying
to build the new Linux, we’ll stick with it.</p>

<p>Our steps therefore:</p>

<ul>
  <li>Select an area of memory where the memory map must be stored as it comes
in from the interrupt. We must be careful not to overwrite other things. However,
this is temporary: once the kernel is booted, it’ll move the memory map to
a different, more suitable location.</li>
  <li>Call the interrupt</li>
  <li>Check the interrupt’s return value:
    <ul>
      <li>If the buffer &gt; 20 bytes, then there is ACPI data. If not, assume
the ACPI value for a usable memory run.</li>
      <li>If the buffer is 0 bytes, the call returned no run and we continue.</li>
      <li>If the <em>Address Range Descriptior</em> has a length of 0, then the BIOS
reported a zero-byte run of memory. We’ll ignore it and continue.</li>
    </ul>
  </li>
  <li>Advance the pointer where the interrupt stores descriptors.</li>
  <li>If a continuation value is present, do it all again.</li>
</ul>

<h2 id="memory-structure">Memory structure</h2>

<p>We’re collecting our list of physical memory runs in the second-stage boot
loader. This information has yet to make it to the kernel, which at this
point hasn’t booted yet. We must therefore create a contract between the 
bootloader and the kernel: a precise definition of what the bootloader
will place in memory, and <em>where</em>. In addition to the address range
descriptors themselves, we’ll also want to tell the kernel how many descriptors
were found. Let’s also stick a magic value on top, just to the kernel can 
verify that the memory map arrived to it unmolested.</p>

<div class="table">
  <table rules="groups">
    <thead>
      <tr>
        <th style="text-align: left">Offset</th>
        <th style="text-align: left">Size</th>
        <th style="text-align: left">Meaning</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: left">0</td>
        <td style="text-align: left">4</td>
        <td style="text-align: left">Magic number, e.g. <code class="language-plaintext highlighter-rouge">0xB007B007</code></td>
      </tr>
      <tr>
        <td style="text-align: left">4</td>
        <td style="text-align: left">4</td>
        <td style="text-align: left">Number of byte runs in the memory map</td>
      </tr>
      <tr>
        <td style="text-align: left">8</td>
        <td style="text-align: left">4</td>
        <td style="text-align: left">Address of the actual map</td>
      </tr>
      <tr>
        <td style="text-align: left">12</td>
        <td style="text-align: left">4</td>
        <td style="text-align: left">Boot drive number (we need to get this to the kernel too, while we’re at it)</td>
      </tr>
      <tr>
        <td style="text-align: left">32</td>
        <td style="text-align: left">16 x runs</td>
        <td style="text-align: left">List of address range descriptors</td>
      </tr>
    </tbody>
  </table>
</div>

<p>In C terms, this’ll look like this:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">struct</span> <span class="n">bootinfo</span>
<span class="p">{</span>
  <span class="kt">uint32_t</span> <span class="n">magic</span><span class="p">;</span>           <span class="c1">// BOOTINFO_MAGIC</span>
  <span class="kt">uint32_t</span> <span class="n">e820_count</span><span class="p">;</span>      <span class="c1">// zero means the BIOS returned nothing</span>
  <span class="kt">uint32_t</span> <span class="n">e820_addr</span><span class="p">;</span>       <span class="c1">// -&gt; struct e820_entry[e820_count]</span>
  <span class="kt">uint32_t</span> <span class="n">boot_drive</span><span class="p">;</span>      <span class="c1">// what the BIOS put in dl at 0x7C00</span>
<span class="p">}</span> <span class="n">__attribute__</span><span class="p">((</span><span class="n">packed</span><span class="p">));</span>

<span class="k">struct</span> <span class="n">e820_entry</span>
<span class="p">{</span>
  <span class="kt">uint32_t</span> <span class="n">base_low</span><span class="p">,</span>   <span class="n">base_high</span><span class="p">;</span>
  <span class="kt">uint32_t</span> <span class="n">length_low</span><span class="p">,</span> <span class="n">length_high</span><span class="p">;</span>
  <span class="kt">uint32_t</span> <span class="n">type</span><span class="p">;</span>
  <span class="kt">uint32_t</span> <span class="n">attrs</span><span class="p">;</span>
<span class="p">}</span> <span class="n">__attribute__</span><span class="p">((</span><span class="n">packed</span><span class="p">));</span>
</code></pre></div></div>

<p>As for <em>where</em> to store this information… here is a list of what
we’ve got going in memory up to the point that we start the kernel:</p>

<div class="table">
  <table rules="groups">
    <thead>
      <tr>
        <th style="text-align: left">Offset</th>
        <th style="text-align: left">Meaning</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td style="text-align: left">0x00000-0x007FF</td>
        <td style="text-align: left">IDT written by 2nd-stage bootloader</td>
      </tr>
      <tr>
        <td style="text-align: left">0x00800-0x00817</td>
        <td style="text-align: left">GDT written by 2nd-stage bootloader</td>
      </tr>
      <tr>
        <td style="text-align: left">below 0x07C00</td>
        <td style="text-align: left">Real-mode stack</td>
      </tr>
      <tr>
        <td style="text-align: left">0x07C00</td>
        <td style="text-align: left">Original boot sector</td>
      </tr>
      <tr>
        <td style="text-align: left">0x08000-0x08320</td>
        <td style="text-align: left">Bootinfo structure</td>
      </tr>
      <tr>
        <td style="text-align: left">0x0EE00-0x0FFFF</td>
        <td style="text-align: left">the FAT (9 sectors), loaded by the first stage</td>
      </tr>
      <tr>
        <td style="text-align: left">0x10000</td>
        <td style="text-align: left">Second-stage bootloader</td>
      </tr>
      <tr>
        <td style="text-align: left">0x20000</td>
        <td style="text-align: left">Kernel</td>
      </tr>
    </tbody>
  </table>
</div>

<p>A diverse collection of things, but it’s important to note that virtually
all of it is important only to the second-stage bootloader. It loaded an IDT
and GDT just to be able to switch to protected mode. It has its own stack,
we have the boot sector floating around as loaded by the BIOS, the FAT table,
and the second stage’s own code. <em>All of this can disappear as soon as the
kernel runs, and the memory it occupies can be released</em>.</p>

<p>I’ve picked <code class="language-plaintext highlighter-rouge">0x8000</code> to place the bootinfo structure, for the simple reason
that it is free. The kernel will know where to pick it up, and then move
it to somewhere more sensible - plenty of options, since just about everything
else will disappear. The kernel will create its own IDT and GDT, and store them
where it wants.</p>

<h2 id="calling-the-bios">Calling the BIOS</h2>

<p>Let’s actually call the BIOS then, and get down to assembly code. We’ll define
a few things:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">BOOTINFO_ADDR</span><span class="w">  </span><span class="o">=</span><span class="w"> </span><span class="mh">0x8000</span><span class="w">        </span><span class="c1"># 32 bytes (only 16 used)</span><span class="w">
</span><span class="n">E820_ADDR</span><span class="w">      </span><span class="o">=</span><span class="w"> </span><span class="mh">0x8020</span><span class="w">        </span><span class="c1"># memory map</span><span class="w">

</span><span class="c1"># 32 entries of 24 bytes = 768 bytes, ending at 0x8320. It's not likely that</span><span class="w">
</span><span class="c1"># real machines will have more entries, but the kernel will warn if that</span><span class="w">
</span><span class="c1"># happens.</span><span class="w">
</span><span class="n">E820_MAX</span><span class="w">       </span><span class="o">=</span><span class="w"> </span><span class="mi">32</span><span class="w"> </span><span class="c1"># entry count</span><span class="w">
</span><span class="n">E820_ENTRY_SZ</span><span class="w">  </span><span class="o">=</span><span class="w"> </span><span class="mi">24</span><span class="w"> </span><span class="c1"># entry size</span><span class="w">
</span><span class="n">SMAP</span><span class="w">           </span><span class="o">=</span><span class="w"> </span><span class="mh">0x534D4150</span><span class="w">    </span><span class="c1"># 'SMAP'; magic signature that the BIOS returns</span><span class="w">
                               </span><span class="c1"># to report the call went well.</span><span class="w">
</span><span class="c1"># A little safety check. The pointer we pass to the kernel is used much later,</span><span class="w">
</span><span class="c1"># so this helps us check that information wasn't clobbered anywhere.</span><span class="w">
</span><span class="n">BOOTINFO_MAGIC</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="mh">0xB007B007</span><span class="w">
</span></code></pre></div></div>

<p>These are all values we’ve gone over above, defined as constants for readability
further on. Neat!</p>

<p>The call to the BIOS, then is done in a loop, since we must retrieve multiple
runs of memory until the BIOS says that there are no more. We’ll do a quick
setup:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">xor</span><span class="w">   </span><span class="nb">ax</span><span class="p">,</span><span class="w"> </span><span class="nb">ax</span><span class="w">                       </span><span class="c1"># ax=0</span><span class="w">
</span><span class="k">mov</span><span class="w">   </span><span class="nb">es</span><span class="p">,</span><span class="w"> </span><span class="nb">ax</span><span class="w">                       </span><span class="c1"># es:di is then a linear address</span><span class="w">
</span><span class="k">mov</span><span class="w">   </span><span class="nb">di</span><span class="p">,</span><span class="w"> </span><span class="n">E820_ADDR</span><span class="w">                </span><span class="c1"># es:di points to the memory map we'll build</span><span class="w">
</span><span class="k">xor</span><span class="w">   </span><span class="nb">ebx</span><span class="p">,</span><span class="w"> </span><span class="nb">ebx</span><span class="w">                     </span><span class="c1"># ebx=0: first call, not a continuation</span><span class="w">
</span><span class="k">xor</span><span class="w">   </span><span class="nb">si</span><span class="p">,</span><span class="w"> </span><span class="nb">si</span><span class="w">                       </span><span class="c1"># si=0: 0 entries stored so far</span><span class="w">
                                   </span><span class="c1">#   (not part of interrupt call)</span><span class="w">
</span></code></pre></div></div>

<p>Now for the loop:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">detect_memory__loop:</span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nb">eax</span><span class="p">,</span><span class="w"> </span><span class="mh">0xE820</span><span class="w">                  </span><span class="c1"># Interrupt subfunction</span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nb">edx</span><span class="p">,</span><span class="w"> </span><span class="n">SMAP</span><span class="w">                    </span><span class="c1"># magic code </span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nb">ecx</span><span class="p">,</span><span class="w"> </span><span class="n">E820_ENTRY_SZ</span><span class="w">           </span><span class="c1"># ask for 24 bytes: 20 of range, plus the</span><span class="w">
                                     </span><span class="c1"># ACPI 3.0 attribute word</span><span class="w">
  </span><span class="k">int</span><span class="w">   </span><span class="mh">0x15</span><span class="w">
</span></code></pre></div></div>

<p>Carry flag means end-of-list, or that E820 is not supported. We stop:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="k">jc</span><span class="w">    </span><span class="n">detect_memory__finished</span><span class="w">
</span></code></pre></div></div>

<p>Let’s check that the magic code (“SMAP”) is present on the response. Otherwise
we give up:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="k">cmp</span><span class="w">   </span><span class="nb">eax</span><span class="p">,</span><span class="w"> </span><span class="n">SMAP</span><span class="w">                    </span><span class="c1"># the BIOS must echo 'SMAP' back</span><span class="w">
  </span><span class="k">jne</span><span class="w">   </span><span class="n">detect_memory__finished</span><span class="w">      </span><span class="c1"># If no 'SMAP', then done.</span><span class="w">
</span></code></pre></div></div>

<p>If the buffer size is 0, it’s not a valid run of memory so we skip it:</p>
<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="k">test</span><span class="w">  </span><span class="nb">ecx</span><span class="p">,</span><span class="w"> </span><span class="nb">ecx</span><span class="w">                     </span><span class="c1"># cx = 0?</span><span class="w">
  </span><span class="k">jz</span><span class="w">    </span><span class="n">detect_memory__next</span><span class="w">          </span><span class="c1"># skip</span><span class="w">
</span></code></pre></div></div>

<p>A little special treatment for ACPI 3.0. We’ve asked for 24 bytes to be returned;
if the BIOS returns only 20, then there’s no ACPI extension. In that case we
just pad the entry to 24 bytes and consider it “in use”.</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="k">cmp</span><span class="w">   </span><span class="nb">ecx</span><span class="p">,</span><span class="w"> </span><span class="mi">20</span><span class="w">
  </span><span class="k">jne</span><span class="w">   </span><span class="n">detect_memory__have_attrs</span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nf">es:</span><span class="p">[</span><span class="nb">di</span><span class="o">+</span><span class="mi">20</span><span class="p">],</span><span class="w"> </span><span class="kt">dword</span><span class="w"> </span><span class="kt">ptr</span><span class="w"> </span><span class="mi">1</span><span class="w">      </span><span class="c1"># A word value of 0x0001: memory in use.</span><span class="w">
</span><span class="nf">detect_memory__have_attrs:</span><span class="w">
</span></code></pre></div></div>

<p>The BIOS may return memory runs of length 0. While these are valid, they
are not useful to us and we skip them:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="c1"># Zero-length regions may be returned but we don't want them. Skip.</span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nb">eax</span><span class="p">,</span><span class="w"> </span><span class="nf">es:</span><span class="p">[</span><span class="nb">di</span><span class="o">+</span><span class="mi">8</span><span class="p">]</span><span class="w">               </span><span class="c1"># length, low half</span><span class="w">
  </span><span class="k">or</span><span class="w">    </span><span class="nb">eax</span><span class="p">,</span><span class="w"> </span><span class="nf">es:</span><span class="p">[</span><span class="nb">di</span><span class="o">+</span><span class="mi">12</span><span class="p">]</span><span class="w">              </span><span class="c1"># ... or high half</span><span class="w">
  </span><span class="k">jz</span><span class="w">    </span><span class="n">detect_memory__next</span><span class="w">          </span><span class="c1"># skip if eax=0</span><span class="w">
</span></code></pre></div></div>

<p>We come to the end of the loop. We keep track of how many runs we’ve found
so far, and if there’s a continuation value, we jump to the loop again.
Otherwise, we are done:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="k">inc</span><span class="w">   </span><span class="nb">si</span><span class="w">                           </span><span class="c1"># +1 areas found</span><span class="w">
  </span><span class="k">add</span><span class="w">   </span><span class="nb">di</span><span class="p">,</span><span class="w"> </span><span class="n">E820_ENTRY_SZ</span><span class="w">            </span><span class="c1"># Move to next position in memory map</span><span class="w">

</span><span class="nf">detect_memory__next:</span><span class="w">
  </span><span class="k">test</span><span class="w">  </span><span class="nb">ebx</span><span class="p">,</span><span class="w"> </span><span class="nb">ebx</span><span class="w">                     </span><span class="c1"># Continuation value of 0: last entry</span><span class="w">
  </span><span class="k">jz</span><span class="w">    </span><span class="n">detect_memory__finished</span><span class="w">      </span><span class="c1"># so we are done.</span><span class="w">
  </span><span class="k">cmp</span><span class="w">   </span><span class="nb">si</span><span class="p">,</span><span class="w"> </span><span class="n">E820_MAX</span><span class="w">                 </span><span class="c1"># out of room; the kernel will warn</span><span class="w">
  </span><span class="k">jb</span><span class="w">    </span><span class="n">detect_memory__loop</span><span class="w">          </span><span class="c1"># LOOP AGAIN if there's room</span><span class="w">
</span></code></pre></div></div>

<p>At this point, we end up with the memory map in memory at our desired
address, i.e. 0x8020. We’ll now prepend the boot information at 0x8000.</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="k">movzx</span><span class="w"> </span><span class="nb">ebx</span><span class="p">,</span><span class="w"> </span><span class="kt">byte</span><span class="w"> </span><span class="kt">ptr</span><span class="w"> </span><span class="n">iBootDrive</span><span class="w">

  </span><span class="k">xor</span><span class="w">   </span><span class="nb">cx</span><span class="p">,</span><span class="w"> </span><span class="nb">cx</span><span class="w">                                 
  </span><span class="k">mov</span><span class="w">   </span><span class="nb">es</span><span class="p">,</span><span class="w"> </span><span class="nb">cx</span><span class="w">                                 
  </span><span class="k">mov</span><span class="w">   </span><span class="nb">di</span><span class="p">,</span><span class="w"> </span><span class="n">BOOTINFO_ADDR</span><span class="w">                      </span><span class="c1"># es:di=0:BOOTINFO_ADDR</span><span class="w">

  </span><span class="k">mov</span><span class="w">   </span><span class="nf">es:</span><span class="p">[</span><span class="nb">di</span><span class="p">],</span><span class="w">    </span><span class="kt">dword</span><span class="w"> </span><span class="kt">ptr</span><span class="w"> </span><span class="n">BOOTINFO_MAGIC</span><span class="w">
  </span><span class="k">movzx</span><span class="w"> </span><span class="nb">ecx</span><span class="p">,</span><span class="w"> </span><span class="nb">ax</span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nf">es:</span><span class="p">[</span><span class="nb">di</span><span class="o">+</span><span class="mi">4</span><span class="p">],</span><span class="w">  </span><span class="nb">ecx</span><span class="w">                        </span><span class="c1"># e820_count</span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nf">es:</span><span class="p">[</span><span class="nb">di</span><span class="o">+</span><span class="mi">8</span><span class="p">],</span><span class="w">  </span><span class="kt">dword</span><span class="w"> </span><span class="kt">ptr</span><span class="w"> </span><span class="n">E820_ADDR</span><span class="w">        </span><span class="c1"># e820_addr</span><span class="w">
  </span><span class="k">mov</span><span class="w">   </span><span class="nf">es:</span><span class="p">[</span><span class="nb">di</span><span class="o">+</span><span class="mi">12</span><span class="p">],</span><span class="w"> </span><span class="nb">ebx</span><span class="w">                        </span><span class="c1"># boot_drive</span><span class="w">
</span></code></pre></div></div>

<p>… and that is that: the full structure is now sitting at 0x8000.</p>

<h2 id="handing-over-to-the-kernel">Handing over to the kernel</h2>

<p>The structure’s ready, but we’re not quite done yet: the kernel has no
idea that the boot info structure exists, much less where it is. This is easy
to remedy: the kernel code simply reads the memory at 0x8000, and consults
the memory map there. That’s not a very robust approach though: if we ever
change the code to place the memory map somewhere else, the both the
bootloader and the kernel must be updated. It’s prettier to pass a pointer
to the kernel, so that the structure placement is entirely the bootloader’s
decision.</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">.macro</span><span class="w"> </span><span class="n">mJumpToKernel</span><span class="w"> </span><span class="n">bootinfo</span><span class="w">
  </span><span class="k">mov</span><span class="w"> </span><span class="nb">ebx</span><span class="p">,</span><span class="w"> </span><span class="nv">\bootinfo</span><span class="w">
  </span><span class="k">jmp</span><span class="w"> </span><span class="mh">0x08</span><span class="p">:</span><span class="mh">0x20000</span><span class="w">
</span><span class="kd">.endm</span><span class="w">
</span></code></pre></div></div>

<p>This give the kernel an additional responsibility though: <strong>it must not
change the ebx register</strong> until the pointer is used. When the time comes
to jump to C code, we simply push <code class="language-plaintext highlighter-rouge">ebx</code> onto the stack and call:</p>

<div class="language-gas highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="w">  </span><span class="k">push</span><span class="w">   </span><span class="nb">ebx</span><span class="w">
  </span><span class="k">call</span><span class="w">   </span><span class="n">kernel_main</span><span class="w">
</span></code></pre></div></div>

<p>and the kernel’s C entry point looks like this:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kt">void</span> <span class="n">kernel_main</span><span class="p">(</span><span class="k">struct</span> <span class="n">bootinfo</span> <span class="o">*</span><span class="n">bi</span><span class="p">)</span>
</code></pre></div></div>

<h2 id="extra-safeguards">Extra safeguards</h2>

<p>When making changes to the bootloader and the kernel’s assembly entry point,
it’s easy to mess up this fragile way of handing the kernel a pointer. We may
inadvertently change the pointer value, or overwrite the memory it points to,
and it’d be difficult to debug when that happens. For this reason, and
extra bonus points, we place a magic value at the boot info structure’s address,
just before the actual boot info - then check it later:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">if</span> <span class="p">(</span><span class="n">handed_over</span> <span class="o">==</span> <span class="mi">0</span> <span class="o">||</span> <span class="n">handed_over</span><span class="o">-&gt;</span><span class="n">magic</span> <span class="o">!=</span> <span class="n">BOOTINFO_MAGIC</span><span class="p">)</span> <span class="p">{</span>
  <span class="n">kprintf</span><span class="p">(</span><span class="s">"bootinfo: BAD MAGIC at %p - no memory map</span><span class="se">\n</span><span class="s">"</span><span class="p">,</span> <span class="p">(</span><span class="kt">uint32_t</span><span class="p">)</span><span class="n">handed_over</span><span class="p">);</span>
  <span class="k">return</span> <span class="mi">0</span><span class="p">;</span>
<span class="p">}</span>
</code></pre></div></div>

<h2 id="getting-the-information-into-the-kernel">Getting the information into the kernel</h2>

<p>At this point, our boot info structure lives at address 0x8000, and
continues to be there as we load the kernel into memory, set up the IDT, GDT,
and jump to protected mode, finally long-jumping to the kernel’s C code.</p>

<p>Before doing anything else in the kernel, we need to “adopt” the boot info
structure, moving it into memory the kernel owns. We do this by copying the data
into the kernel’s <code class="language-plaintext highlighter-rouge">.bss</code> section, which is the section for uninitialized
variables. With that done, the data is safe. We can then mark the area at 0x8000
as “available”!</p>

<h2 id="summary">Summary</h2>

<p>Somewhere down the line, we’ll want our kernel to manage the system’s memory,
handing it out to processes as they start, and checking that those processes
aren’t naughty and try to write beyond their allocated memory. Before we’re 
in a position to do so, however, the first thing to do is to create a map
of the existing physical memory: how much of it is there, and which parts
are reserved? Some of the memory is ROM, other memory is mapped to physical
devices, yet other memory might be faulty. The BIOS can provide us with this
information, so it is important we call it while we’re still in real mode - 
in protected mode, we can’t talk to the BIOS anymore.</p>

<p>In this section, we show how to call BIOS interrupt <code class="language-plaintext highlighter-rouge">0x15/E820</code> repeatedly
to populate a physical memory map (in real mode). After we jump to protected
mode, we then have the kernel move it to an area of its choosing, finally
freeing up all the memory that was used by the second-stage boot loader, 
boot sector, and FAT tables.</p>

<p><a href="/operating-system-development-interrupts.html" class="btn">Continue on to the next part of this guide!</a></p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="osdev" /><category term="asm" /><summary type="html"><![CDATA[It has been a while since there we any updates to this, the in-depth guide to toy operating system development! But oh well, what’s thirteen years between friends? When last we were here, we had built first and second-stage boot loaders, and a kernel that said “Hello world”, then hung. It’s high time to move on. In this section, we’ll be looking at the system’s memory map. As we’ll soon need to write memory management (to be done by our brand new kernel), we’ll need to know which areas of memory we can touch, and which are off-limits. Overwriting the kernel itself, for example, would be bad, and overwriting the global interrupt table would bring the system down, as well. This article is part of a series on toy operating system development. View the series index]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/monolith.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/monolith.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Mercator: gridded earth data as map tiles</title><link href="http://www.independent-software.com/mercator-gridded-earth-data-as-tiles.html" rel="alternate" type="text/html" title="Mercator: gridded earth data as map tiles" /><published>2026-06-11T07:00:00+00:00</published><updated>2026-06-11T07:00:00+00:00</updated><id>http://www.independent-software.com/mercator-gridded-earth-data-as-tiles</id><content type="html" xml:base="http://www.independent-software.com/mercator-gridded-earth-data-as-tiles.html"><![CDATA[<p>A few years ago I wrote a post about <a href="/fast-uniform-vector-grids-with-scattered-data-interpolation-in-csharp.html">generating current-flow animations on map tiles from sparse vector data</a>. I’ve since
built a number of applications that had to deal with showing physical earth data on a map, 
and eventually I’ve put what I know together into an actual product: <strong><a href="https://mercator.blue">mercator</a></strong>, a gridded earth data API that serves weather, ocean, air quality and elevation data as map tiles.</p>

<!--more-->

<p><img src="https://mercator.blue/og-default.png" alt="mercator: gridded earth data as tiles" class="mercator-logo" /></p>

<h1 id="the-problem">The problem</h1>

<p>There are a number of (paid) APIs on the internet that you can call to get
data for a single lat/lon point on earth. You can obtain, say, ocean salinity
at that point, or wave height, or wind direction and speed. But in order to
show data on a map, you’ll want a grid of points, probably as many as 100x100, 
to render a smooth surface on your map. That would mean calling a point API
10,000 times, which is (a) very slow an (b) likely costly.</p>

<p>What’s needed here is a grid of points that you can download in a single API
call, and then you do the interpolation between these points to present
a smooth surface. This shouldn’t be hard to get - data offered by NOAA’s GFS,
ocean state from HYCOM, air quality from Copernicus CAMS, elevation from
GEBCO - it’s all already in grid form, just not in a suitable format for
browser consumption. It’s heavy, world-spanning NetCDF files, or GRIBs. The
missing piece is a way to get this data into the browser efficiently.</p>

<h1 id="values-baked-into-pixels">Values baked into pixels</h1>

<p><em>The</em> way to render data on a map is through map tiles. Using tiles, a massive
raster can be delivered to the browser in a lazy way: when the users zooms,
or pans (sufficiently), the map requests map tiles from the server and renders
these. Only the data for the region that the user is looking at is downloaded,
and only at the required zoom level. At any given time, 5-10 map tiles are
downloaded (depending on the user’s screen resolution), and the total download
is usually not more than ~100KB.</p>

<p>With map tiles established as the way to get data onto a map, the trick then 
is to pour all the NetCDF and GRIB data from different providers into map
tiles, regularly (with data updated every 6 hours). Having such tiles at hand
already solves part of the problem. But there’s a twist: we do better by 
not producing raster tiles that show an immutable image, but by encoding
<em>values</em> into the image’s pixels. If each pixel doesn’t represent a color
but a value, then the <em>browser</em> can decide how to map that value to a color
on the user’s map.</p>

<p>This means that a dataset such as air temperature could be rendered in shades
of blue, or using a red gradient, or a rainbow gradient, and the user could
switch between these colors on the fly. All that’s necessary is to put
a bit WebGL in the rendering pipeline that translates values to colors. Better
yet, wind or ocean current speed tiles could encode not just scalar values,
but vector <em>u</em> and <em>v</em> values. With wind <em>direction</em> known, a bit of WebGL
code can render animated particles on a map, fast!</p>

<p>This approach isn’t new: Mapbox’s terrain RGB uses this, too. What’s new 
is applying it to a variety of datasets (ocean current speed, wind speed,
water temperature etc.) and updating the information every 6 hours. Elevation
can be offered as well (Mapbox-style), and doesn’t need refreshing every
6 hours, of course.</p>

<h1 id="about-mercator">About Mercator</h1>

<p>The product that offers all this is <a href="mercator.blue">mercator.blue</a>. It has two
halves: the first is the <strong>tile service</strong>: an HTTP endpoint serving the value-encoded tiles plus a <code class="language-plaintext highlighter-rouge">metadata.json</code> that fully documents the encoding, so any developer can decode the pixels without my code. The second is an <strong>open-source SDK</strong> that ships the shader decoders and ready-made visualisations (colormapped rasters, animated wind and current streamlines, arrows, contours, value labels) for <a href="https://mercator.blue/quickstart/maplibre/">MapLibre, Mapbox, Leaflet, OpenLayers, deck.gl and React</a>. 
If you decide to use one of these SDKs, then a few lines of code are enough
to get an animated wind field or ocean current particles on a map.</p>

<p>Mercator offers a catalogue of datasets, all updated every 6 hours (with the
exception of elevation, which is static). There is atmospheric weather, ocean currents and waves, air quality and elevation, all including forecasts (12h ahead, 24h ahead, 48h ahead).
The whole thing follows the same shape as Mapbox GL JS or Deck.gl: the SDK is free and open (Apache-2.0), and the paid part is the data API, with a free tier of 10,000 tiles a month. Because the tile format is documented, you are never locked to my renderer.</p>

<h1 id="try-it-out">Try it out</h1>

<p>You’re welcome to test drive both the datasets and the SDK. The SDK is
open source; the tiles have a free tier that allows you to experiment all the
datasets (it’s 10K tiles free).</p>

<p>There is a live interactive globe on the <a href="https://mercator.blue">homepage</a> with wind streaming over it, a <a href="https://mercator.blue/quickstart/maplibre/">live playground for each framework</a>, and the full <a href="https://mercator.blue/docs">tile-encoding and API docs</a> if you want to decode the tiles yourself.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="javascript" /><summary type="html"><![CDATA[A few years ago I wrote a post about generating current-flow animations on map tiles from sparse vector data. I’ve since built a number of applications that had to deal with showing physical earth data on a map, and eventually I’ve put what I know together into an actual product: mercator, a gridded earth data API that serves weather, ocean, air quality and elevation data as map tiles.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/currents.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/currents.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Getting your PHP backend to finally send email</title><link href="http://www.independent-software.com/getting-backend-to-finally-send-email.html" rel="alternate" type="text/html" title="Getting your PHP backend to finally send email" /><published>2024-04-11T10:11:00+00:00</published><updated>2024-04-11T10:11:00+00:00</updated><id>http://www.independent-software.com/getting-backend-to-finally-send-email</id><content type="html" xml:base="http://www.independent-software.com/getting-backend-to-finally-send-email.html"><![CDATA[<p>You’re developing a back-end in PHP (Laravel, Lumen, or just freewheeling it)
and you want it to send out email when users use your “forgot password” 
functionality. Getting everything configured just right can be a headache
and this article lists all the things you need to do. You could also reach
for a third-party solution, but then you’d have to have your credit card handy.</p>

<!--more-->

<h1 id="using-a-3rd-party-service">Using a 3rd-party service?</h1>

<p>If you don’t want to code the email sending yourself, you can reach for a 
third-party solution. <a href="https://www.mailgun.com/">Mailgun</a>, <a href="https://sendgrid.com/">Sendgrid</a> and <a href="https://mailchimp.com/">Mailchimp</a> come to mind, but they
all cost money. Mailgun has a free tier, but it’ll only work for sending out
email to up to 5 known email addresses, and that’s not what you want - you
want to send email out into the world (but only one email at a time). Even if 
you did pay for a third-party solution, it may have a free tier of up to, say, 
1,000 emails per month, after which you start paying. God forbid that your API 
key falls into the wrong hands and someone sends out a million emails with it!</p>

<h1 id="using-your-own-server">Using your own server</h1>

<p>In my case, I have a shared-hosting server that runs PHP. Through CPanel, I
am able to create email addresses, so I can go ahead and create 
<code class="language-plaintext highlighter-rouge">info@myserver.org</code> and use that to send email from.</p>

<h2 id="problem-1-email-sent-manually-from-my-server-does-not-arrive">Problem 1: Email sent manually from my server does not arrive</h2>

<p>With so many spammers around, email has become something like the Wild West. 
Anyone can send out emails, and users are bombarded with spam. To fight some 
of this, email providers try to block emails where it can’t be determined where
the email came from - in which case it could be a spoofed address.</p>

<p>Sending out a simple email manually from my CPanel email client to a GMail 
address will result in this (I’ll get an email back from CPanel or from Gmail):</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>550-5.7.26 This message does not pass authentication checks (SPF and DKIM both 
550-5.7.26 do not pass).
550-5.7.26 This mail is unauthenticated, which poses a security risk to the 
550-5.7.26 sender and Gmail users, and has been blocked. The sender must 
550-5.7.26 authenticate with at least one of SPF or DKIM. For this message, 
550-5.7.26 DKIM checks did not pass and SPF check for [example.com] 
550-5.7.26 did not pass with ip: [x.y.z.n]. The sender should visit 
550-5.7.26 https://support.google.com/mail/answer/81126#authentication for 
550 5.7.26 instructions on setting up authentication.
</code></pre></div></div>

<p>In other words, if your domain doesn’t have <a href="https://postmarkapp.com/guides/spf">SPF</a> and <a href="https://postmarkapp.com/guides/dkim">DKIM</a> records, GMail (and
likely others) will reject your mails straight out of the gate.</p>

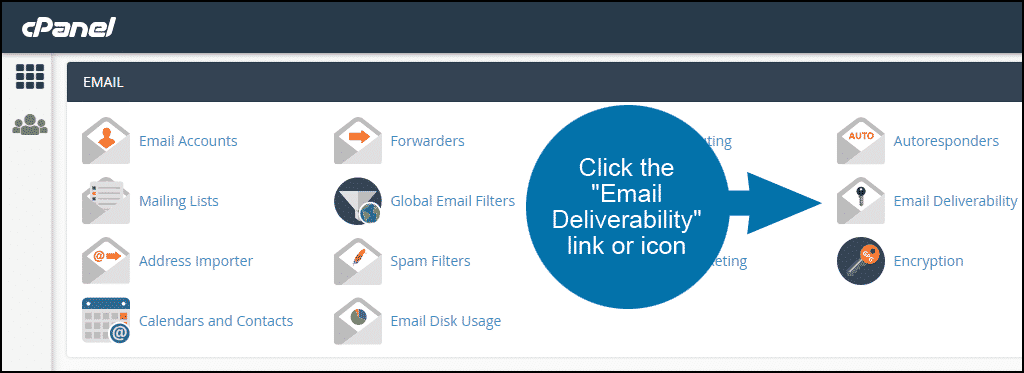
<p>A solution is brought by CPanel itself: the <strong>Email deliverability</strong> option.</p>

<p><img src="https://www.greengeeks.com/support/wp-content/uploads/2019/04/cPanel-select-section-EMAIL-deliverability-01.png" alt="Accessing Email Deliverability on CPanel" /></p>

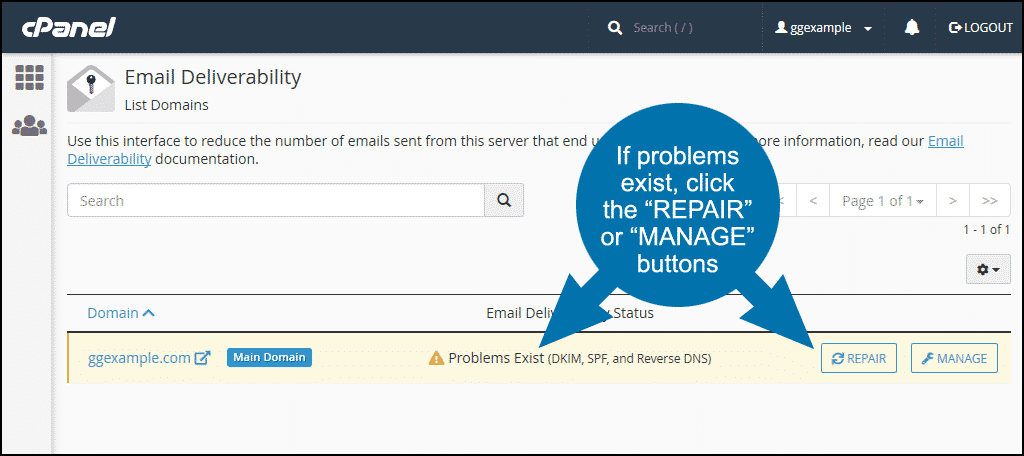
<p>If you have no DKIM or SPF records setup, then the Email Deliverabilty screen 
will report that there is a problem and offer to repair it:</p>

<p><img src="https://www.greengeeks.com/support/wp-content/uploads/2019/04/cPanel-email-deliverability-01.png" alt="Repaint DKIM problem" /></p>

<p>If your DNS is actually under CPanel’s control, you can CPanel create SPF
and DKIM records automatically. If not, and like me, you have your domain
at GoDaddy while you’re hosting somewhere else, it’s not going to be automatic.
But never fear, CPanel can still help. If you choose the <strong>Manage</strong> option,
CPanel will tell you that no DKIM record exists, and provide you with a suggested
record:</p>

<blockquote>
  <p>This system does not control DNS for the “myserver.org” domain and the system 
did not find any authoritative nameservers for this domain. You can install the 
suggested “DKIM” record locally. However, this server is not the authoritative 
nameserver. If you install this record, this change will not be effective. 
Contact your domain registrar to verify this domain’s registration.</p>
</blockquote>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Suggested DKIM (TXT) record:
Name = default._domainkey.www.myserver.org.
Value = v=DKIM1; k=rsa; p=a-long-encrypted-value;
</code></pre></div></div>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Suggested SPF (TXT) record:
Name = www.myserver.org.
Value = v=spf1 +mx +a +ip4:(ip number) ~all
</code></pre></div></div>

<p>You can actually take these values to GoDaddy and create the DNS records
yourself. Note that both need to be <strong>TXT</strong> records. Create these and save
them, wait a few minutes, and then manually send an email again. It should
now arrive without issue into a GMail inbox.</p>

<h2 id="getting-laravels-mailer-to-behave">Getting Laravel’s mailer to behave</h2>

<p>With the TXT records configured, I found that while I could send emails
manually through the email web client and receive them, emails from PHP
would not be received.</p>

<p>It turns out that for Lumen, after configuring <a href="https://lumen.laravel.com/docs/10.x/mail">all that’s necessary</a> for <code class="language-plaintext highlighter-rouge">Illuminate/mail</code>, no email would be sent. I also found
that the email sending route returns rather quickly; ordinarily it would be
processing a little while before returning.</p>

<p>I there checked my STMP settings using the <a href="https://www.gmass.co/smtp-test">GMass SMTP Test Tool</a>
which came in handy. I found that I was able to send email email through this
and receive it in a GMail inbox, so my SMTP settings were correct. I also
noted that sending the email took a few seconds, so it was suspicious that
the Laravel code returned immediately.</p>

<p>Finding no way to get the Laravel code to tell me why it failed, I installed
the venerable <a href="https://github.com/PHPMailer/PHPMailer">PHPMailer</a> instead. Testing
it out by pasting its sample code into my back-end implementation, it immediately worked.</p>

<p>Stepping away from Laravel’s SwiftMailer was made easier by using Laravel’s <code class="language-plaintext highlighter-rouge">ENV</code>
variables in PHPMailer instead of using hardcoded values (these are the settings 
from the <code class="language-plaintext highlighter-rouge">.env</code> file):</p>

<div class="language-php highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">Host</span>       <span class="o">=</span> <span class="nf">env</span><span class="p">(</span><span class="s1">'MAIL_HOST'</span><span class="p">);</span>            <span class="c1">// Set the SMTP server to send through</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">SMTPAuth</span>   <span class="o">=</span> <span class="kc">true</span><span class="p">;</span>                        <span class="c1">// Enable SMTP authentication</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">Username</span>   <span class="o">=</span> <span class="nf">env</span><span class="p">(</span><span class="s1">'MAIL_USERNAME'</span><span class="p">);</span>        <span class="c1">// SMTP username</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">Password</span>   <span class="o">=</span> <span class="nf">env</span><span class="p">(</span><span class="s1">'MAIL_PASSWORD'</span><span class="p">);</span>        <span class="c1">// SMTP password</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">SMTPSecure</span> <span class="o">=</span> <span class="nc">PHPMailer</span><span class="o">::</span><span class="no">ENCRYPTION_SMTPS</span><span class="p">;</span> <span class="c1">// Enable implicit TLS encryption</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">Port</span>       <span class="o">=</span> <span class="nf">env</span><span class="p">(</span><span class="s1">'MAIL_PORT'</span><span class="p">,</span> <span class="mi">2525</span><span class="p">);</span>      <span class="c1">// TCP port</span>
</code></pre></div></div>

<p>Further, it’s still possible to use Laravel’s Blade templates by rendering them
to string:</p>

<div class="language-php highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$mail</span><span class="o">-&gt;</span><span class="nf">isHTML</span><span class="p">(</span><span class="kc">true</span><span class="p">);</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">Subject</span> <span class="o">=</span> <span class="s1">'Database password reset'</span><span class="p">;</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nc">Body</span>    <span class="o">=</span> <span class="nf">view</span><span class="p">(</span><span class="s1">'reset'</span><span class="p">,</span> <span class="nb">compact</span><span class="p">(</span><span class="s1">'user'</span><span class="p">))</span><span class="o">-&gt;</span><span class="nf">render</span><span class="p">();</span>
<span class="nv">$mail</span><span class="o">-&gt;</span><span class="nf">send</span><span class="p">();</span>
</code></pre></div></div>

<p>I know I’ve had Laravel’s SwiftMailer work for me in the past, but PHPMailer
does me the courtesy of letting me put a <code class="language-plaintext highlighter-rouge">try</code>…<code class="language-plaintext highlighter-rouge">catch</code> around the mail sending
process so that I’ll know when it’s failed. Also, a full SMTP debug can be 
echoed to the output to see precisely what went wrong.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="php" /><summary type="html"><![CDATA[You’re developing a back-end in PHP (Laravel, Lumen, or just freewheeling it) and you want it to send out email when users use your “forgot password” functionality. Getting everything configured just right can be a headache and this article lists all the things you need to do. You could also reach for a third-party solution, but then you’d have to have your credit card handy.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/email.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/email.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Denthor/Asphyxia’s VGA trainers: Texture mapping</title><link href="http://www.independent-software.com/denthor-asphyxia-vga-trainer-21-texture-mapping.html" rel="alternate" type="text/html" title="Denthor/Asphyxia’s VGA trainers: Texture mapping" /><published>2023-02-06T16:32:00+00:00</published><updated>2023-02-06T16:32:00+00:00</updated><id>http://www.independent-software.com/denthor-asphyxia-vga-trainer-21-texture-mapping</id><content type="html" xml:base="http://www.independent-software.com/denthor-asphyxia-vga-trainer-21-texture-mapping.html"><![CDATA[<p>This trainer is on texture mapping. I know, I know, I said light sourcing, then 
Gouraud, then texture mapping, but I got enough mail (a deluge in fact ;) 
telling me to do texture mapping.</p>

<!--more-->

<div style="background:steelblue; color: white; border-top: solid 1px #333; border-bottom: solid 1px #333; padding-bottom: 32px; margin-bottom: 32px;">

  <pre style="background: none; text-align: center">
DENTHOR, coder for ...
_____   _____   ____   __   __  ___  ___ ___  ___  __   _____
/  _  \ /  ___&gt; |  _ \ |  |_|  | \  \/  / \  \/  / |  | /  _  \
|  _  | \___  \ |  __/ |   _   |  \    /   &gt;    &lt;  |  | |  _  |
\_/ \_/ &lt;_____/ |__|   |__| |__|   |__|   /__/\__\ |__| \_/ \_/
smith9@batis.bis.und.ac.za
The great South African Demo Team! Contact us for info/code exchange!  
</pre>

  <p style="text-align:center; font-weight: bold">Grant Smith, alias Denthor of Asphyxia, wrote up several articles on the 
creation of demo effects in the 90s. I reproduce them here, as they offer
so much insight into the demo scene of the time.
</p>

  <p style="text-align: center">
These articles apply some formatting to Denthor's original ASCII files, plus
a few typo fixes.
</p>

</div>

<h2 id="free-direction-texture-mapping">Free Direction Texture Mapping</h2>

<p>There are two things you should know before we begin.</p>

<p>Firstly, I am cheating. The texture mapping I am going to show you is not
perspective-correct, with clever divides for z-placement etc. This method
looks almost as good and is quite a bit faster too.</p>

<p>Secondly, you will find it all rather easy. The reason for this is that it’s
all rather simple. I first made the routine by sitting down with some paper
and a pencil and had it on the machine in a few hours. A while later when
people on the net started discussing their methods, they were remarkably
similar.</p>

<p>Let me show you what I mean.</p>

<p>Let us assume you have a texture of 128x128 (a straight array of bytes
<code class="language-plaintext highlighter-rouge">[0..127, 0..127]</code>) which you want to map onto the side of a polygon. The
problem of course being that the polygon can be all over the place, with
one side longer then the other etc.</p>

<p>Our first step is to make sure we know which end is up. Let me
demonstrate:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                      1
                    +
                 /    \
              /         \
          4 +            +  2
              \        /
                \   /
                  +
                  3
</code></pre></div></div>

<p>Let us say that the above is the chosen polygon. We have decided that point
1 is the top left, point 3 is bottom right. This means that</p>

<ul>
  <li>1 - 2   is the top of the texture</li>
  <li>2 - 3   is the right of the texture</li>
  <li>3 - 4   is the bottom of the texture</li>
  <li>4 - 1   is the left of the texture</li>
</ul>

<p>The same polygon, but rotated:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                      3
                    +
                 /    \
              /         \
          2 +            +  4
              \        /
                \   /
                  +
                  1
</code></pre></div></div>

<p>Although the positions of the points are different, point 1 is still the
top-left of our texture.</p>

<h2 id="how-to-put-it-to-screen">How to put it to screen</h2>

<p>Okay, so now you have four points and know which one of them is also the 
top-left of our texture. What next?</p>

<p>If you think back to our tutorial on polygons, you will remember we draw it
scanline by scanline. We do texture mapping the same way.</p>

<p>Let’s look at that picture again:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                      1
                    +
               a /    \  b
              /         \
          4 +            +  2
              \        /
                \   /
                  +
                  3
</code></pre></div></div>

<p>We know that point 1 is at <code class="language-plaintext highlighter-rouge">[0,0]</code> in our texture. Point 2 is at <code class="language-plaintext highlighter-rouge">[127,0]</code>,
Point 3 is at <code class="language-plaintext highlighter-rouge">[127,127]</code>, and point 4 is at <code class="language-plaintext highlighter-rouge">[0,127]</code>.</p>

<p>The clever bit, and the entire key to texture mapping, is making the
logical leap that precisely half way between Point 1 and Point 2 (b), we are at
<code class="language-plaintext highlighter-rouge">[64,0]</code> in our texture. (a) is in the same manner at <code class="language-plaintext highlighter-rouge">[0,64]</code>.</p>

<p>That’s it. All we need to know per y scanline is:</p>

<ul>
  <li>The starting position on the x axis of the polygon line</li>
  <li>The position on the x in the texture map referenced by that point</li>
  <li>The position on the y in the texture map referenced by that point</li>
  <li>The ending position on the x axis of the polygon line</li>
  <li>The position on the x in the texture map referenced by that point</li>
  <li>The position on the y in the texture map referenced by that point</li>
</ul>

<p>Let me give you an example. Let’s say that (a) and (b) from the above
picture are on the same y scanline. We know that the x of that scanline is
(say) 100 pixels at the start and 200 pixels at the end, making it’s width
100 pixels.</p>

<p>We know that on the left hand side, the texture is at <code class="language-plaintext highlighter-rouge">[0,64]</code>, and at the
right hand side, the texture is at <code class="language-plaintext highlighter-rouge">[64,0]</code>. In 100 pixels we have to
traverse our texture from <code class="language-plaintext highlighter-rouge">[0,64]</code> to <code class="language-plaintext highlighter-rouge">[64,0]</code>.</p>

<p>Assume at the start we have figured out the starting and ending points in
the texture:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  <span class="n">textureX</span> <span class="p">=</span> <span class="m">0</span><span class="p">;</span>
  <span class="n">textureY</span> <span class="p">=</span> <span class="m">64</span><span class="p">;</span>
  <span class="n">textureEndX</span> <span class="p">=</span> <span class="m">64</span><span class="p">;</span>
  <span class="n">textureEndY</span> <span class="p">=</span> <span class="m">0</span><span class="p">;</span>

  <span class="n">dx</span> <span class="p">:=</span> <span class="p">(</span><span class="n">TextureEndX</span><span class="p">-</span><span class="n">TextureX</span><span class="p">)/(</span><span class="n">maxx</span><span class="p">-</span><span class="n">minx</span><span class="p">);</span>
  <span class="n">dy</span> <span class="p">:=</span> <span class="p">(</span><span class="n">TextureEndY</span><span class="p">-</span><span class="n">TextureY</span><span class="p">)/(</span><span class="n">maxx</span><span class="p">-</span><span class="n">minx</span><span class="p">);</span>
  <span class="k">for</span> <span class="n">loop1</span> <span class="p">:=</span> <span class="n">minx</span> <span class="k">to</span> <span class="n">maxx</span> <span class="k">do</span> <span class="k">BEGIN</span>
    <span class="n">PutPixel</span> <span class="p">(</span><span class="n">loop1</span><span class="p">,</span> <span class="n">ypos</span><span class="p">,</span> <span class="n">texture</span> <span class="p">[</span><span class="n">textureX</span><span class="p">,</span> <span class="n">textureY</span><span class="p">],</span> <span class="n">VGA</span><span class="p">);</span>
    <span class="n">textureX</span> <span class="p">=</span> <span class="n">textureX</span> <span class="p">+</span> <span class="n">dx</span><span class="p">;</span>
    <span class="n">textureY</span> <span class="p">=</span> <span class="n">textureY</span> <span class="p">+</span> <span class="n">dy</span><span class="p">;</span>
  <span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>Do the above for all the scanlines, and you have a texture mapped polygon!
It’s that simple.</p>

<p>We find our beginning and ending positions in the usual fashion. We know
that Point 1 is <code class="language-plaintext highlighter-rouge">[0,0]</code>. We know that Point 2 is <code class="language-plaintext highlighter-rouge">[127,0]</code>. We know the number
of scanlines on the y axis between Point 1 and Point 2.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  textureDX = 127/abs (point2.y - point1.y)
</code></pre></div></div>

<p>We run though all the y scanlines, starting from <code class="language-plaintext highlighter-rouge">[0,0]</code> and adding the above
formula to the X every time. When we hit the last scanline, we will be at
point <code class="language-plaintext highlighter-rouge">[127,0]</code> in the texture.</p>

<p>Repeat for all four sides, and you have the six needed variables per
scanline.</p>

<h2 id="in-closing">In closing</h2>

<p>As you can see, texture mapping (this type at least) is quite easy, and
produces quite a good result. You will however notice a bit of distortion
if you bring the polygon too close. This can be fixed by a) Subdividing the
polygon, so the one is made up of four or more smaller polygons. Much
bigger, but works; b) Using more accurate fixed point; or c) Figuring out
perspective correct texture mapping, mapping along constant-z lines etc.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="demo" /><summary type="html"><![CDATA[This trainer is on texture mapping. I know, I know, I said light sourcing, then Gouraud, then texture mapping, but I got enough mail (a deluge in fact ;) telling me to do texture mapping.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/demoscene.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/demoscene.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Denthor/Asphyxia’s VGA trainers: Hidden face removal</title><link href="http://www.independent-software.com/denthor-asphyxia-vga-trainer-20-hidden-face-removal.html" rel="alternate" type="text/html" title="Denthor/Asphyxia’s VGA trainers: Hidden face removal" /><published>2023-02-06T16:27:00+00:00</published><updated>2023-02-06T16:27:00+00:00</updated><id>http://www.independent-software.com/denthor-asphyxia-vga-trainer-20-hidden-face-removal</id><content type="html" xml:base="http://www.independent-software.com/denthor-asphyxia-vga-trainer-20-hidden-face-removal.html"><![CDATA[<p>This trainer is on 3D hidden face removal and face sorting. I was going to
add shading, but that can wait until a later trainer. For convenience I
will build on the 3D code from <a href="/denthor-asphyxia-vga-trainer-8-3d-visualization.html">Part 8</a>. The maths for 
face removal is a bit tricky, but just think back to your old high school 
trigonometry classes.</p>

<!--more-->

<div style="background:steelblue; color: white; border-top: solid 1px #333; border-bottom: solid 1px #333; padding-bottom: 32px; margin-bottom: 32px;">

  <pre style="background: none; text-align: center">
DENTHOR, coder for ...
_____   _____   ____   __   __  ___  ___ ___  ___  __   _____
/  _  \ /  ___&gt; |  _ \ |  |_|  | \  \/  / \  \/  / |  | /  _  \
|  _  | \___  \ |  __/ |   _   |  \    /   &gt;    &lt;  |  | |  _  |
\_/ \_/ &lt;_____/ |__|   |__| |__|   |__|   /__/\__\ |__| \_/ \_/
smith9@batis.bis.und.ac.za
The great South African Demo Team! Contact us for info/code exchange!  
</pre>

  <p style="text-align:center; font-weight: bold">Grant Smith, alias Denthor of Asphyxia, wrote up several articles on the 
creation of demo effects in the 90s. I reproduce them here, as they offer
so much insight into the demo scene of the time.
</p>

  <p style="text-align: center">
These articles apply some formatting to Denthor's original ASCII files, plus
a few typo fixes.
</p>

</div>

<h2 id="face-sorting">Face Sorting</h2>

<p>There are many ways to sort faces in a 3D object. For now, I will show you
just about the easiest one of the lot.</p>

<p>Say you have two polygons….</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                ------P1

           ------------------P2

                   Eye
</code></pre></div></div>

<p>As you can see, <code class="language-plaintext highlighter-rouge">P1</code> has to be drawn before <code class="language-plaintext highlighter-rouge">P2</code>. The easiest way to do this is
as follows:</p>

<p>On startup, find the midpoint of each of the polys, through the easy
equations:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>x = (P2.1.x + P2.2.x + P2.3.x + p2.4.x)/4
y = (P2.1.y + P2.2.y + P2.3.y + p2.4.y)/4
z = (P2.1.z + P2.2.z + P2.3.z + p2.4.z)/4
</code></pre></div></div>

<p>NOTE: For a triangle you would obviously only use three points and divide
by three.</p>

<p>Anyway, now you have the X,Y,Z of the midpoint of the polygon. You can then
rotate this point with the others. When it is time to draw, you can
compare the resulting Z of the midpoint, sort all of the Z items, and then
draw them from back to front.</p>

<p>In the sample program I use a simple bubble sort… basically, I check the
first two values against each other, and swap them if the first is bigger
than the second. I continue doing this to all the numbers until I run
through the entire list without swapping once. Bubble sorts are standard
computer science topics… perhaps borrow a text book to find out
more about them and other (better) sorting methods.</p>

<p>The above isn’t perfect, but it should work 90% of the time. But it still
means that when you are drawing a cube, you have to draw all 6 sides every
frame, even though only three or so are visible. That is where hidden face
removal comes in…</p>

<h2 id="hidden-face-removal">Hidden Face Removal</h2>

<p>Pick up something square. A stiffy disk will do fine. Face it towards you,
and number all the corners from one to four in a clockwise direction.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                1 +-------------+ 2
                  |             |
                  |             |
                  |             |
                  |             |
                4 +-------------+ 3
</code></pre></div></div>

<p>Now rotate the stiffy disk on all three axes, making sure that you can
still see the front of the disk. You will notice that whenever you can see
the front of the disk, the four points are still in alphabetical order. Now
rotate it so that you can see the back of the stiffy. Your points will now
be:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                2 +-------------+ 1
                  |             |
                  |             |
                  |             |
                  |             |
                3 +-------------+ 4
</code></pre></div></div>

<p>The points are now anti-clockwise! This means, in its simplest form, that
if you define all your polygon points in a clockwise order, when drawing you
ignore the polys that are anticlockwise. (Obviously when you define the 3D
object, you define the polygons facing away from you in an anticlockwise
order.)</p>

<p>To find out whether a poly’s points are clockwise or not, we need to find
its normal. Here is where things start getting fun.</p>

<p>In school, you are told that a normal is perpendicular to the plane. In
ASCII:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                      | Normal
                      |
                      |
        --------------------------- Polygon
</code></pre></div></div>

<p>As you can see, the normal is at 90 degrees to the surface of the poly. We
must extend this to three dimensions for our polygons. You’ll have to trust
me on that, I can’t draw it in ASCII :)</p>

<p>To find a normal, you only need three points from your poly (ABC):</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>A(x0,y0,z0), B(X1,Y1,Z1), C(X2,Y2,Z2)
</code></pre></div></div>

<p>then the vector normal = AB^AC = (Xn,Yn,Zn) with</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Xn=(y1-y0)(z0-z2)-(z1-z0)(y0-y2)
Yn=(z1-z0)(x0-x2)-(x1-x0)(z0-z2)
Zn=(x1-x0)(y0-y2)-(y1-y0)(x0-x2)
</code></pre></div></div>

<p>We are interested in the Z normal, so we will use the function:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>normal:=(x1-x0)(y0-y2)-(y1-y0)(x0-x2);
</code></pre></div></div>

<p>The result is something of a sine wave when you rotate the poly in three
dimensions. A negative value means that the poly is facing you, a positive
value means that it is pointing away.</p>

<p>The above means that with a mere two MULs you can discount an entire poly
and not draw it. This method is perfect for “closed” objects such as cubes
etc.</p>

<p>I am anything but a maths teacher, so go borrow someone’s math book to find
out more about surface normals. Trust me, there is a lot more written about
them than you think.</p>

<p>An extension of calculating your normal is finding out about light-sourcing
your polygons. Watch for more information in one of the next few trainers.</p>

<p>A combination of the above two routines should work quite nicely in
creating 3d objects with little or no overlapping.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="demo" /><summary type="html"><![CDATA[This trainer is on 3D hidden face removal and face sorting. I was going to add shading, but that can wait until a later trainer. For convenience I will build on the 3D code from Part 8. The maths for face removal is a bit tricky, but just think back to your old high school trigonometry classes.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/demoscene.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/demoscene.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Denthor/Asphyxia’s VGA trainers: Flame effect</title><link href="http://www.independent-software.com/denthor-asphyxia-vga-trainer-19-flame-effect.html" rel="alternate" type="text/html" title="Denthor/Asphyxia’s VGA trainers: Flame effect" /><published>2023-02-06T16:11:00+00:00</published><updated>2023-02-06T16:11:00+00:00</updated><id>http://www.independent-software.com/denthor-asphyxia-vga-trainer-19-flame-effect</id><content type="html" xml:base="http://www.independent-software.com/denthor-asphyxia-vga-trainer-19-flame-effect.html"><![CDATA[<p>This trainer is on assembler. For those people who already know assembler 
quite well, this tutorial is also on the flame effect.</p>

<!--more-->

<div style="background:steelblue; color: white; border-top: solid 1px #333; border-bottom: solid 1px #333; padding-bottom: 32px; margin-bottom: 32px;">

  <pre style="background: none; text-align: center">
DENTHOR, coder for ...
_____   _____   ____   __   __  ___  ___ ___  ___  __   _____
/  _  \ /  ___&gt; |  _ \ |  |_|  | \  \/  / \  \/  / |  | /  _  \
|  _  | \___  \ |  __/ |   _   |  \    /   &gt;    &lt;  |  | |  _  |
\_/ \_/ &lt;_____/ |__|   |__| |__|   |__|   /__/\__\ |__| \_/ \_/
smith9@batis.bis.und.ac.za
The great South African Demo Team! Contact us for info/code exchange!  
</pre>

  <p style="text-align:center; font-weight: bold">Grant Smith, alias Denthor of Asphyxia, wrote up several articles on the 
creation of demo effects in the 90s. I reproduce them here, as they offer
so much insight into the demo scene of the time.
</p>

  <p style="text-align: center">
These articles apply some formatting to Denthor's original ASCII files, plus
a few typo fixes.
</p>

</div>

<h2 id="assembler---the-short-version">Assembler - the short version</h2>

<p>Okay, there are many assembler trainers out there, many of which are
probably better than this one. I will focus on the areas of assembler that
I find important… if you want more, go buy a book (go for the Michael
Abrash ones), or scour the ‘net for others.</p>

<p>First, let us start off with the basic set up of an assembler program.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">DOSSEG</span>
</code></pre></div></div>

<p>This tells your assembler program to order your segments in the same manner
that high level languages do.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">.MODEL</span> <span class="o">&lt;</span><span class="nv">MODEL</span><span class="o">&gt;</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">&lt;MODEL&gt;</code> can be:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Tiny       Code + Data &lt; 64k   (Can be made a COM file)
Small      Code &lt; 64k          Data &lt; 64k
Medium     Code &gt; 64k          Data &lt; 64k
Compact    Code &lt; 64k          Data &gt; 64k
Large      Code &gt; 64k          Data &gt; 64k
Huge       Arrays &gt; 64k
</code></pre></div></div>

<p>Enable 286 instructions … can be <code class="language-plaintext highlighter-rouge">.386</code> ; <code class="language-plaintext highlighter-rouge">.386P</code> etc.:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">.286</span>
</code></pre></div></div>

<p>Set the stack. <code class="language-plaintext highlighter-rouge">&lt;size&gt;</code> will be the size of your stack. I usually use <code class="language-plaintext highlighter-rouge">200h</code>:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">.STACK</span> <span class="o">&lt;</span><span class="nb">si</span><span class="nv">ze</span><span class="o">&gt;</span>
</code></pre></div></div>

<p>Tells the program that the data is about to follow. (Everything after this
will be placed in the data segment):</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">.DATA</span>
</code></pre></div></div>

<p>Tells the program that the code is about to follow. (Everything after this
will be placed in the code segment)</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">.CODE</span>
</code></pre></div></div>

<p>Tells the program that this is where the code begins:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nl">START:</span>
</code></pre></div></div>

<p>Tells the program that this is where the code ends:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">END</span> <span class="nv">START</span>
</code></pre></div></div>

<p>To compile and run an assembler file, we run:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>tasm bob
tlink bob
</code></pre></div></div>

<p>I personally use <code class="language-plaintext highlighter-rouge">tasm</code>; you will have to find out how your assembler works.</p>

<p>Now, if we ran the above file as follows:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">DOSSEG</span>
<span class="nf">.MODEL</span> <span class="nv">SMALL</span>
<span class="nf">.286</span>
<span class="nf">.STACK</span> <span class="mh">200h</span>
<span class="nf">.DATA</span>
<span class="nf">.CODE</span>

<span class="nf">START</span>
<span class="nf">END</span> <span class="nv">START</span>
</code></pre></div></div>

<p>You would think that is would just exit to DOS immediately, right? Wrong.
You have to specifically give DOS back control, by doing the following:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">START</span>
        <span class="nf">mov</span>     <span class="nb">ax</span><span class="p">,</span><span class="mh">4c00h</span>
        <span class="nf">int</span>     <span class="mh">21h</span>
<span class="nf">END</span> <span class="nv">START</span>
</code></pre></div></div>

<p>Now if you compiled it, it would run and do nothing.</p>

<p>Okay, let us kick off with registers.</p>

<p>Firstly: A bit is a value that is either 1 or 0.</p>

<p>This is obviously quite limited, but if we start counting in them, we can
get larger numbers. Counting with ones and zeros is known as binary, and we
call it base 2. Counting in normal decimal is known as base 10, and
counting in hexadecimal is known as base 16.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    Base 2 (Binary)     Base 10 (Decimal)    Base 16 (Hexadecimal)
         0                      0                       0
         1                      1                       1
         10                     2                       2
         11                     3                       3
         100                    4                       4
         101                    5                       5
         110                    6                       6
         111                    7                       7
         1000                   8                       8
         1001                   9                       9
         1010                   10                      A
         1011                   11                      B
         1100                   12                      C
         1101                   13                      D
         1110                   14                      E
         1111                   15                      F
</code></pre></div></div>

<p>As you can see, you need four bits to count up to 15, and we call this a
<em>nibble</em>. With eight bits, we can count up to 255, and we call this a <em>byte</em>.
With sixteen bits, we can count up to 65535, and we call this a <em>word</em>. With
thirty-two bits, we can count up to lots, and we call this a <em>double word</em>.</p>

<p>A quick note: Converting from binary to hexadecimal is actually quite easy. You
break up the binary into groups of four bits, starting on the right, and
convert these groups of four to hex.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>      1010 0010 1111 0001
  =      A    2    F    1
</code></pre></div></div>

<p>Converting to decimal is a bit more difficult. What you do, is you multiply
each number by its base to the power of its index…</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  A2F1 hex
= (A*16^3) + (2*16^2) + (F*16^1) + (1*16^0)
= (10*4096) + (2*256) + (15*16) + (1)
= 40960 + 512 + 240 + 1
= 41713 decimal
</code></pre></div></div>

<p>The same system can be used for binary.</p>

<p>To convert from decimal to another base, you divide the decimal value by the
desired base, keeping a note of the remainders, and then read the results
backwards.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>               16   |   41713
               16   |   2607    r   1       (41713 / 16 = 2607 r 1)
               16   |   162     r   F       (2607 / 16 = 162 r 15)
               16   |   10      r   2       (162 / 16 = 10 r 2)
                    |   0       r   A       (10 / 16 = 0 r 10)
</code></pre></div></div>

<p>Read the remainders backwards, our number is <code class="language-plaintext highlighter-rouge">A2F1</code> hex. Again, the same
method can be used for binary.</p>

<p>The reason why hex is popular is obvious: using bits, it is impossible
to get a reasonable base 10 (decimal) system going, and binary gets unwieldly
at high values. Don’t worry too much though: most assemblers (like <code class="language-plaintext highlighter-rouge">tasm</code>)
will convert all your decimal values to hex for you.</p>

<p>You have four general purpose registers: <code class="language-plaintext highlighter-rouge">AX</code>, <code class="language-plaintext highlighter-rouge">BX</code>, <code class="language-plaintext highlighter-rouge">CX</code> and <code class="language-plaintext highlighter-rouge">DX</code>.
Think of them as variables that you will always have. On a 286, these
registers are 16 bytes long, or one <em>word</em>.</p>

<p>As you know, a <em>word</em> consists of two bytes, and in assembler you can access
these bytes individually. They are separated into high bytes and low bytes per
word.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>   High byte | Low byte
   0000 0000 | 0000 0000  bits
   [--------Word-------]
</code></pre></div></div>

<p>The method of access is easy. The high byte of <code class="language-plaintext highlighter-rouge">AX</code> is <code class="language-plaintext highlighter-rouge">AH</code>, and the low byte is
<code class="language-plaintext highlighter-rouge">AL</code>. You can also access <code class="language-plaintext highlighter-rouge">BH</code>, <code class="language-plaintext highlighter-rouge">BL</code>, <code class="language-plaintext highlighter-rouge">CH</code>, <code class="language-plaintext highlighter-rouge">CL</code>, <code class="language-plaintext highlighter-rouge">DH</code> and <code class="language-plaintext highlighter-rouge">DL</code>.</p>

<p>A 386 has extended registers: <code class="language-plaintext highlighter-rouge">EAX</code>, <code class="language-plaintext highlighter-rouge">EBX</code>, <code class="language-plaintext highlighter-rouge">ECX</code>, <code class="language-plaintext highlighter-rouge">EDX</code>… you can access the
lower word normally (as <code class="language-plaintext highlighter-rouge">AX</code>, with bytes <code class="language-plaintext highlighter-rouge">AH</code> and <code class="language-plaintext highlighter-rouge">AL</code>), but you cannot access the
high word directly … you must <code class="language-plaintext highlighter-rouge">ror EAX,16</code> (rotate the binary value through
16 bits), after which the high word and low word swap … do it again to
return them. Acessing <code class="language-plaintext highlighter-rouge">EAX</code> as a whole is no problem: 
<code class="language-plaintext highlighter-rouge">mov eax, 10; add eax,ebx</code> … these are all valid.</p>

<p>Next come segments. As you have probably heard, computer memory is divided
into various 64k segments (note: 64k = 65,536 bytes, sound familiar?) A
segment register points to which segment you are looking at. An offset
register points to how far into that segment you are looking. One way
of looking at it is like looking at a 2D array… the segments are your
columns and your offsets are your rows. Segments and offsets are displayed
as Segment:Offset … so <code class="language-plaintext highlighter-rouge">$a000:50</code> would mean the fiftieth byte in segment
<code class="language-plaintext highlighter-rouge">$a000</code>.</p>

<p>The segment registers are <code class="language-plaintext highlighter-rouge">ES</code>, <code class="language-plaintext highlighter-rouge">DS</code>, <code class="language-plaintext highlighter-rouge">SS</code> and <code class="language-plaintext highlighter-rouge">CS</code>. A 386 also has <code class="language-plaintext highlighter-rouge">FS</code> and <code class="language-plaintext highlighter-rouge">GS</code>.
These values are words (0-65,535), and you cannot access the high or low bytes
separately. <code class="language-plaintext highlighter-rouge">CS</code> points to your code segment, and usually if you touch this
your program will explode. <code class="language-plaintext highlighter-rouge">SS</code> points to your stack segment, again, this
baby is dangerous. <code class="language-plaintext highlighter-rouge">DS</code> points to your data segment, and can be altered, if
you put it back after you use it, and don’t use any global variables while
it is altered. <code class="language-plaintext highlighter-rouge">ES</code> is your extra segment, and you can do what you want with
it.</p>

<p>The offset registers are <code class="language-plaintext highlighter-rouge">DI</code>, <code class="language-plaintext highlighter-rouge">SI</code>, <code class="language-plaintext highlighter-rouge">IP</code>, <code class="language-plaintext highlighter-rouge">SP</code>, <code class="language-plaintext highlighter-rouge">BP</code>. Offset registers are generally
associated with specific segment registers, as follows:
<code class="language-plaintext highlighter-rouge">ES:DI</code>  <code class="language-plaintext highlighter-rouge">DS:SI</code>  <code class="language-plaintext highlighter-rouge">CS:IP</code>  <code class="language-plaintext highlighter-rouge">SS:SP</code> … On a 286, <code class="language-plaintext highlighter-rouge">BX</code> can be used instead of the above
offset registers, and on a 386, any register may be used. <code class="language-plaintext highlighter-rouge">DS:BX</code> is therefore
valid.</p>

<p>If you create a global variable (let’s say <code class="language-plaintext highlighter-rouge">bob</code>), when you access that
variable, the compiler will actually look for it in the data segment.
This means that the statement:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ax = bob
</code></pre></div></div>

<p>could be</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>ax = ds:[15]
</code></pre></div></div>

<p>A quick note: A value may be signed or unsigned. An unsigned word has a
range from 0 to 65,535. A signed word is called an <em>integer</em> and has a range
-32,768 to 32,767. With a signed value, if the leftmost bit is equal to 1,
the value is in the negative.</p>

<p>Next, let us have a look at the stack. Let us say that you want to save the
value in <code class="language-plaintext highlighter-rouge">ax</code>, use <code class="language-plaintext highlighter-rouge">ax</code> to do other things, then restore it to its origional
value afterwards. This is done by utilizing the stack. Have a look at the
following code:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">mov</span>   <span class="nb">ax</span><span class="p">,</span> <span class="mi">50</span>      <span class="c1">; ax is equal to 50</span>
<span class="nf">push</span>  <span class="nb">ax</span>          <span class="c1">; push ax onto the stack</span>
<span class="nf">mov</span>   <span class="nb">ax</span><span class="p">,</span> <span class="mi">27</span>      <span class="c1">; ax is equal to 27</span>
<span class="nf">pop</span>   <span class="nb">ax</span>          <span class="c1">; pop ax off the stack</span>
</code></pre></div></div>

<p>At this point, <code class="language-plaintext highlighter-rouge">ax</code> is equal to 50.</p>

<p>Remember we defined the stack to be <code class="language-plaintext highlighter-rouge">200h</code> further up? This is part of the
reason we have it. When you push a value onto the stack, that value is
recorded on the stack heap (referenced by <code class="language-plaintext highlighter-rouge">SS:SP</code>, <code class="language-plaintext highlighter-rouge">SP</code> is incremented) When you
pop a value off the stack, the value is placed into the variable you are
popping it back in to, <code class="language-plaintext highlighter-rouge">SP</code> is decremented and so forth. Note that the computer
does not care what you pop the value back into.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">mov</span>   <span class="nb">ax</span><span class="p">,</span> <span class="mi">50</span>
<span class="nf">push</span>  <span class="nb">ax</span>
<span class="nf">pop</span>   <span class="nb">bx</span>
</code></pre></div></div>

<p>This would set the values of both <code class="language-plaintext highlighter-rouge">ax</code> and <code class="language-plaintext highlighter-rouge">bx</code> to <code class="language-plaintext highlighter-rouge">50</code>. (There are faster ways 
of doing this, pushing and popping are fairly fast though).</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">push</span> <span class="nb">ax</span>
<span class="nf">push</span> <span class="nb">bx</span>
<span class="nf">pop</span>  <span class="nb">ax</span>
<span class="nf">pop</span>  <span class="nb">bx</span>
</code></pre></div></div>

<p>This would swap the values of <code class="language-plaintext highlighter-rouge">ax</code> and <code class="language-plaintext highlighter-rouge">bx</code>. As you can see, to pop the values back
in to the original variables, you must pop them back in the opposite
direction to which you pushed them.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">push</span> <span class="nb">ax</span>
<span class="nf">push</span> <span class="nb">bx</span>
<span class="nf">push</span> <span class="nb">cx</span>

<span class="nf">pop</span> <span class="nb">cx</span>
<span class="nf">pop</span> <span class="nb">bx</span>
<span class="nf">pop</span> <span class="nb">ax</span>
</code></pre></div></div>

<p>would result in no change for any of the registers.</p>

<p>When a procedure is called, all the parameters for that procedure are pushed
onto the stack. These can actually be read right off the stack, if you want
to.</p>

<p>As you have already seen, the <code class="language-plaintext highlighter-rouge">mov</code> command moves a value…</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">mov</span>  <span class="o">&lt;</span><span class="nv">dest</span><span class="o">&gt;</span><span class="p">,</span> <span class="o">&lt;</span><span class="nv">source</span><span class="o">&gt;</span>
</code></pre></div></div>

<p>Note that <code class="language-plaintext highlighter-rouge">dest</code> and <code class="language-plaintext highlighter-rouge">source</code> must be the same number of bits long.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">mov</span>  <span class="nb">ax</span><span class="p">,</span> <span class="nb">dl</span>
</code></pre></div></div>

<p>would not work, and neither would</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">mov</span>  <span class="nb">cl</span><span class="p">,</span><span class="nb">bx</span>
</code></pre></div></div>

<p>However:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">mov</span>  <span class="nb">cx</span><span class="p">,</span><span class="nb">dx</span>
<span class="nf">mov</span>  <span class="nb">ax</span><span class="p">,</span><span class="mi">50</span>
<span class="nf">mov</span>  <span class="nb">es</span><span class="p">,</span><span class="nb">ax</span>
</code></pre></div></div>

<p>are all valid.</p>

<p><code class="language-plaintext highlighter-rouge">shl</code> I have explained before, it is where all the bits in a register are
shifted one to the left and a zero added on to the right. This is the
equivalent of multiplying the value by two. <code class="language-plaintext highlighter-rouge">shr</code> works in the opposite
direction.</p>

<p><code class="language-plaintext highlighter-rouge">rol</code> does the same, except that the bit that is removed from the left is
replaced on the right hand side. <code class="language-plaintext highlighter-rouge">ror</code> works in the opposite direction.</p>

<p><code class="language-plaintext highlighter-rouge">div &lt;value&gt;</code> divides the value in <code class="language-plaintext highlighter-rouge">ax</code> by value and returns the result in
<code class="language-plaintext highlighter-rouge">al</code> if value is a byte, placing the remainder in <code class="language-plaintext highlighter-rouge">ah</code>. If value is a word,
the double word <code class="language-plaintext highlighter-rouge">DX:AX</code> is divided by value, the result being placed in <code class="language-plaintext highlighter-rouge">ax</code>
and the remainder in <code class="language-plaintext highlighter-rouge">dx</code>. Note that this only works for unsigned values.</p>

<p><code class="language-plaintext highlighter-rouge">idiv &lt;value&gt;</code> does the same as above, but for signed variables.</p>

<p><code class="language-plaintext highlighter-rouge">mul &lt;value&gt;</code>  If value is a byte, <code class="language-plaintext highlighter-rouge">al</code> is multiplied by value and the result
is stored in <code class="language-plaintext highlighter-rouge">ax</code>. If value is a word, <code class="language-plaintext highlighter-rouge">ax</code> is multiplied by value and the
result is stored in the double word <code class="language-plaintext highlighter-rouge">DX:AX</code>.</p>

<p><code class="language-plaintext highlighter-rouge">imul &lt;value&gt;</code> does the same as above, but for signed variables.</p>

<p>The <code class="language-plaintext highlighter-rouge">j*</code> commands are fairly simple: if a condition is met, jump to a certain
label.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">jz</span>  <span class="o">&lt;</span><span class="nv">label</span><span class="o">&gt;</span>   <span class="nv">Jump</span> <span class="nv">if</span> <span class="nv">zero</span>
<span class="nf">ja</span>  <span class="o">&lt;</span><span class="nv">label</span><span class="o">&gt;</span>   <span class="nv">Jump</span> <span class="nv">above</span>     <span class="p">(</span><span class="nv">unsigned</span><span class="p">)</span>
<span class="nf">jg</span>  <span class="o">&lt;</span><span class="nv">label</span><span class="o">&gt;</span>   <span class="nv">Jump</span> <span class="nv">greater</span>   <span class="p">(</span><span class="nb">si</span><span class="nv">gned</span><span class="p">)</span>
</code></pre></div></div>

<p>and so forth.</p>

<p>An example:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">cmp</span>  <span class="n">ax</span><span class="p">,</span><span class="m">50</span>    <span class="p">;</span> <span class="n">Compare</span> <span class="n">ax</span> <span class="k">to</span> <span class="m">50</span>
<span class="n">je</span>   <span class="p">@</span><span class="n">Equal</span>   <span class="p">;</span> <span class="k">If</span> <span class="n">they</span> <span class="n">are</span> <span class="n">equal</span><span class="p">,</span> <span class="n">jump</span> <span class="k">to</span> <span class="k">label</span> <span class="p">@</span><span class="n">equal</span>
<span class="n">call</span> <span class="n">MyProc</span>   <span class="p">;</span> <span class="n">Runs</span> <span class="k">procedure</span> <span class="n">MyProc</span> <span class="k">and</span> <span class="k">then</span> <span class="n">returns</span> <span class="k">to</span> <span class="n">the</span> <span class="n">next</span> <span class="n">line</span> <span class="k">of</span> <span class="n">code</span><span class="p">.</span>
</code></pre></div></div>

<p>Procedures are declared as follows:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">MyProc</span>   <span class="nv">proc</span> <span class="nv">near</span>
         <span class="nf">ret</span>    <span class="c1">; Must be here to return from where it was called</span>
<span class="nf">MyProc</span>   <span class="nv">endp</span>
</code></pre></div></div>

<p>Variables are also easy:</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">bob</span>  <span class="nv">db</span> <span class="mi">50</span>
</code></pre></div></div>

<p>creates a variable <code class="language-plaintext highlighter-rouge">bob</code>, a byte, with an initial value of 50.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">bob2</span> <span class="nv">dw</span> <span class="mi">50</span>
</code></pre></div></div>

<p>creates a variable <code class="language-plaintext highlighter-rouge">bob2</code>, a word, with an initial value of 50.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">bob3</span> <span class="nv">db</span> <span class="mi">1</span><span class="p">,</span><span class="mi">2</span><span class="p">,</span><span class="mi">3</span><span class="p">,</span><span class="mi">4</span><span class="p">,</span><span class="mi">5</span><span class="p">,</span><span class="mi">65</span><span class="p">,</span><span class="mi">23</span>
</code></pre></div></div>

<p>creates <code class="language-plaintext highlighter-rouge">bob3</code>, an array of 7 bytes.</p>

<div class="language-nasm highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">bob4</span> <span class="nv">db</span> <span class="mi">100</span> <span class="nv">dup</span> <span class="p">(</span><span class="nv">?</span><span class="p">)</span>
</code></pre></div></div>

<p>creates <code class="language-plaintext highlighter-rouge">bob4</code>, an array of 100 bytes, with no starting value.</p>

<p>Go back and look at <a href="/denthor-asphyxia-vga-trainer-7-animation.html">Part 7</a> for a whole lot more assembler commands, and get
some sort of reference guide to help you out with others. I personally use
the Norton Guides help file to program assembler.</p>

<h2 id="fire-routines">Fire Routines</h2>

<p>To demonstrate how to write an assembler program, we will write a fire
routine in 100% assembler. The theory is simple.</p>

<p>Set the palette to go from white to yellow to red to blue to black.
Create a 2D array representing the screen on the computer.
Place high values at the bottom of the array (screen)
for each element, do the following:</p>

<ul>
  <li>Take the average of the four elements under it:</li>
</ul>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                         * Current element
                        123
                         4  Other elements
</code></pre></div></div>

<ul>
  <li>Get the average of the four elements, and place the result in the current element.</li>
  <li>Repeat</li>
</ul>

<p>Easy, no? I first saw a fire routine in the Iguana demo, and I just had to
do one ;) … it looks very effective.</p>

<p>With the sample file, I have created a batch file, <code class="language-plaintext highlighter-rouge">make.bat</code>. It basically
says:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>tasm fire
tlink fire
</code></pre></div></div>

<p>So to build and run the fire program, type:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>make
fire
</code></pre></div></div>

<p>The source file is commented quite well, so there shouldn’t be any problems.</p>

<h2 id="in-closing">In closing</h2>

<p>As you can see, the sample program is in 100% assembler. For the next tutorial
I will return to Pascal, and hopefully your newfound assembler skills will
help you there too.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="demo" /><summary type="html"><![CDATA[This trainer is on assembler. For those people who already know assembler quite well, this tutorial is also on the flame effect.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/demoscene.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/demoscene.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Denthor/Asphyxia’s VGA trainers: File packing</title><link href="http://www.independent-software.com/denthor-asphyxia-vga-trainer-18-file-packing.html" rel="alternate" type="text/html" title="Denthor/Asphyxia’s VGA trainers: File packing" /><published>2023-02-06T15:22:00+00:00</published><updated>2023-02-06T15:22:00+00:00</updated><id>http://www.independent-software.com/denthor-asphyxia-vga-trainer-18-file-packing</id><content type="html" xml:base="http://www.independent-software.com/denthor-asphyxia-vga-trainer-18-file-packing.html"><![CDATA[<p>This trainer is about reading PCX files, file packing, and putting everything 
into one executable file.</p>

<!--more-->

<div style="background:steelblue; color: white; border-top: solid 1px #333; border-bottom: solid 1px #333; padding-bottom: 32px; margin-bottom: 32px;">

  <pre style="background: none; text-align: center">
DENTHOR, coder for ...
_____   _____   ____   __   __  ___  ___ ___  ___  __   _____
/  _  \ /  ___&gt; |  _ \ |  |_|  | \  \/  / \  \/  / |  | /  _  \
|  _  | \___  \ |  __/ |   _   |  \    /   &gt;    &lt;  |  | |  _  |
\_/ \_/ &lt;_____/ |__|   |__| |__|   |__|   /__/\__\ |__| \_/ \_/
smith9@batis.bis.und.ac.za
The great South African Demo Team! Contact us for info/code exchange!  
</pre>

  <p style="text-align:center; font-weight: bold">Grant Smith, alias Denthor of Asphyxia, wrote up several articles on the 
creation of demo effects in the 90s. I reproduce them here, as they offer
so much insight into the demo scene of the time.
</p>

  <p style="text-align: center">
These articles apply some formatting to Denthor's original ASCII files, plus
a few typo fixes.
</p>

</div>

<h2 id="loading-a-pcx-file">Loading a PCX file</h2>

<p>This is actually quite easy. The PCX file is divided into three sections,
namely a 128 byte header, a data section, and a 768 byte palette.</p>

<p>You can usually ignore the 128 byte header, but here it is:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>0  Manufacturer     10 = ZSoft .PCX file
1  Version
2  Encoding
3  Bits Per Pixel
4  XMin, Ymin, XMax, YMax  (2 bytes each)
12 Horizontal Resolution (2 bytes)
14 Vertical Resolution (2 bytes)
16 Color palette setting (48 bytes)
64 Reserved
65 Number of color planes
66 Bytes per line (2 bytes)
68 1 = Color    2 = Grayscale  (2 bytes)
70 Blank (58 bytes)
</code></pre></div></div>

<p>That makes 128 bytes.</p>

<p>The palette file, which is 768 bytes, is situated at the very end of the
PCX file. The 769’th byte back should be the decimal 12, which indicates
that a VGA color palette is to follow.</p>

<p>There is one thing that we have to do to get the palette correct in VGA…
the PCX palette values for R,G,B are 0 to 255 respectively. To convert this
to our standard (VGA) palette, we must divide the R,G,B values by 4, to get
them into a range of 0 to 63.</p>

<p>Actually decoding the image is very simple. Starting after the 128 byte
header, we read a byte.</p>

<p>If the top two bits of this byte are not set, we dump the value to the screen.</p>

<p>We check bits as follows:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>if ((temp and $c0) = $c0) then ...(bits are set)... else ...(bits are not set)
</code></pre></div></div>
<p>C0 in hex = 11000000 in binary = 192 in decimal</p>

<p>Let’s look at that more closely…</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  temp  and  c0h
  temp  and  11000000b
</code></pre></div></div>

<p>That means, when represented in bit format, both corresponding bits have
to be set to one for the result to be one.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>0 and 0 = 0     1 and 0 = 0    0 and 1 = 0    1 and 1 = 1
</code></pre></div></div>

<p>In the above case then, both of the top two bits of temp have to be set for
the result to equal <code class="language-plaintext highlighter-rouge">11000000b</code>. If it does not equal that, the top two bits
are not both set, and we can put the pixel.</p>

<p>So:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  <span class="k">if</span> <span class="p">((</span><span class="n">temp</span> <span class="k">and</span> <span class="mh">$c0</span><span class="p">)</span> <span class="p">=</span> <span class="mh">$c0</span><span class="p">)</span> <span class="k">then</span> <span class="k">BEGIN</span>
  <span class="k">END</span> <span class="k">else</span> <span class="k">BEGIN</span>
    <span class="n">putpixel</span> <span class="p">(</span><span class="n">screenpos</span><span class="p">,</span><span class="m">0</span><span class="p">,</span><span class="n">temp</span><span class="p">,</span><span class="n">vga</span><span class="p">);</span>
    <span class="k">inc</span> <span class="p">(</span><span class="n">screenpos</span><span class="p">);</span>
  <span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>If the top two bits <em>are</em> set, things change. The bottom six bits become
a loop counter, which the next byte is repeated.</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  <span class="k">if</span> <span class="p">((</span><span class="n">temp</span> <span class="k">and</span> <span class="mh">$c0</span><span class="p">)</span> <span class="p">=</span> <span class="mh">$c0</span><span class="p">)</span> <span class="k">then</span> <span class="k">BEGIN</span>
    <span class="cm">{ Read in next byte, temp2 here.}</span>
    <span class="k">for</span> <span class="n">loop1</span><span class="p">:=</span><span class="m">1</span> <span class="k">to</span> <span class="p">(</span><span class="n">temp</span> <span class="k">and</span> <span class="mh">$3f</span><span class="p">)</span> <span class="k">do</span> <span class="k">BEGIN</span>
      <span class="n">putpixel</span> <span class="p">(</span><span class="n">screenpos</span><span class="p">,</span><span class="m">0</span><span class="p">,</span><span class="n">temp2</span><span class="p">,</span><span class="n">vga</span><span class="p">);</span>
      <span class="k">inc</span> <span class="p">(</span><span class="n">screenpos</span><span class="p">);</span>
    <span class="k">END</span><span class="p">;</span>
  <span class="k">END</span> <span class="k">else</span> <span class="k">BEGIN</span>
    <span class="n">putpixel</span> <span class="p">(</span><span class="n">screenpos</span><span class="p">,</span><span class="m">0</span><span class="p">,</span><span class="n">temp</span><span class="p">,</span><span class="n">vga</span><span class="p">);</span>
    <span class="k">inc</span> <span class="p">(</span><span class="n">screenpos</span><span class="p">);</span>
  <span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>There is our PCX loader. You will note that by and’ing <code class="language-plaintext highlighter-rouge">temp</code> by <code class="language-plaintext highlighter-rouge">$3f</code>; I am
and’ing it by <code class="language-plaintext highlighter-rouge">00111111b</code>… in other words, clearing the top two bits.</p>

<p>The sample program has the above in assembler, but it is the same procedure…
and you can read the next tutorial for more info on how to code in assembler.</p>

<p>In the sample I assume that the pic is 320x200, with a maximum size of 66,432
bytes.</p>

<h2 id="file-packing">File packing</h2>

<p>The question is simple: how do I get all my files into one executable?
Having many small data files can start to look unprofessional.</p>

<p>An easy way to have one .exe and one .dat file when dealing with many
cels etc. is easy… you would alter your load procedure, which looks
as follows:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">VAR</span> <span class="n">temp</span> <span class="p">:</span> <span class="k">Array</span> <span class="p">[</span><span class="m">1..5</span><span class="p">,</span><span class="m">1..256</span><span class="p">]</span> <span class="k">of</span> <span class="kt">byte</span><span class="p">;</span>
<span class="k">Procedure</span> <span class="n">Init</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic1.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">1</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic2.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">2</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic3.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">3</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic4.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">4</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic5.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">5</span><span class="p">]);</span>
<span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>For one compile you would do this:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">VAR</span> <span class="n">temp</span> <span class="p">:</span> <span class="k">Array</span> <span class="p">[</span><span class="m">1..5</span><span class="p">,</span><span class="m">1..256</span><span class="p">]</span> <span class="k">of</span> <span class="kt">byte</span><span class="p">;</span>
<span class="k">Procedure</span> <span class="n">Init</span><span class="p">;</span>
<span class="k">VAR</span> <span class="n">f</span><span class="p">:</span><span class="k">File</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic1.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">1</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic2.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">2</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic3.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">3</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic4.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">4</span><span class="p">]);</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'pic5.cel'</span><span class="p">,</span><span class="n">temp</span><span class="p">[</span><span class="m">5</span><span class="p">]);</span>
  <span class="n">assign</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="s">'pic.dat'</span><span class="p">);</span>
  <span class="n">rewrite</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="m">1</span><span class="p">);</span>
  <span class="n">blockwrite</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="n">temp</span><span class="p">,</span><span class="n">sizeof</span><span class="p">(</span><span class="n">temp</span><span class="p">));</span>
  <span class="n">close</span> <span class="p">(</span><span class="n">f</span><span class="p">);</span>
<span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>From then on, you would do:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">VAR</span> <span class="n">temp</span> <span class="p">:</span> <span class="k">Array</span> <span class="p">[</span><span class="m">1..5</span><span class="p">,</span><span class="m">1..256</span><span class="p">]</span> <span class="k">of</span> <span class="kt">byte</span><span class="p">;</span>
<span class="k">Procedure</span> <span class="n">Init</span><span class="p">;</span>
<span class="k">VAR</span> <span class="n">f</span><span class="p">:</span><span class="k">File</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="n">assign</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="s">'pic.dat'</span><span class="p">);</span>
  <span class="n">reset</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="m">1</span><span class="p">);</span>
  <span class="n">blockread</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="n">temp</span><span class="p">,</span><span class="n">sizeof</span><span class="p">(</span><span class="n">temp</span><span class="p">));</span>
  <span class="n">close</span> <span class="p">(</span><span class="n">f</span><span class="p">);</span>
<span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>This means that instead of five data files, you now have one! You have also
stripped the 800 byte cel header too. Note that this will work for any
form of data, not just cel files.</p>

<p>The next logical step is to include this data in the .exe file, but the
question is how?  In an earlier tutorial, I converted my data file to
constants and placed it inside my main program. This is not good mainly
because of space restrictions … you can only have so many constants, and
what if your data file is two megs big?</p>

<p>Attached with this tutorial is a solution. I have written a program that
combines your data files with your executable file, no matter how big
the data is. The only thing you have to worry about is a small change in
your data loading methods. Let’s find out what.</p>

<h2 id="using-the-file-packer">Using the file packer</h2>

<p>Normally you would load your data as follows:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">Procedure</span> <span class="n">Init</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="s">'bob.bob'</span><span class="p">,</span><span class="n">temp</span><span class="p">);</span>
  <span class="n">loadpcx</span> <span class="p">(</span><span class="s">'den.pcx'</span><span class="p">,</span><span class="n">VGA</span><span class="p">);</span>        <span class="cm">{ Load a PCX file }</span>
  <span class="n">loaddat</span> <span class="p">(</span><span class="s">'data.dat'</span><span class="p">,</span><span class="n">lookup</span><span class="p">);</span>    <span class="cm">{ Load raw data into lookup }</span>
<span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>Easy, hey? Now, using the file packer, you would change this to:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">USES</span> <span class="n">fpack</span><span class="p">;</span>
<span class="k">Procedure</span> <span class="n">Init</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="n">total</span> <span class="p">:=</span> <span class="m">3</span><span class="p">;</span>
  <span class="n">infodat</span><span class="p">[</span><span class="m">1</span><span class="p">]</span> <span class="p">:=</span> <span class="s">'bob.bob'</span><span class="p">;</span>
  <span class="n">infodat</span><span class="p">[</span><span class="m">2</span><span class="p">]</span> <span class="p">:=</span> <span class="s">'den.pcx'</span><span class="p">;</span>
  <span class="n">infodat</span><span class="p">[</span><span class="m">3</span><span class="p">]</span> <span class="p">:=</span> <span class="s">'data.dat'</span><span class="p">;</span>
  <span class="n">loadcel</span> <span class="p">(</span><span class="m">1</span><span class="p">,</span><span class="n">temp</span><span class="p">);</span>
  <span class="n">loadpcx</span> <span class="p">(</span><span class="m">2</span><span class="p">,</span><span class="n">VGA</span><span class="p">);</span>
  <span class="n">loaddat</span> <span class="p">(</span><span class="m">3</span><span class="p">,</span><span class="n">lookup</span><span class="p">);</span>
<span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>Not too difficult? Now, this is still using the normal data files on your
hard drive. You would then run PACK.EXE, select the program’s .exe as the
base, then select “bob.bob”, “den.pcx” and “data.dat”, in order (1, 2, 3).
Hit “c” to contine, and it will combine the files. Your programs .exe file
will be able to run independently of the separate data files on disk,
because the data files are imbedded with the .exe.</p>

<p>Let us take a closer look at the load procedures. Normally a load procedure
would look as follows:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">Procedure</span> <span class="n">LoadData</span> <span class="p">(</span><span class="n">name</span><span class="p">:</span><span class="k">string</span><span class="p">;</span> <span class="n">p</span><span class="p">:</span><span class="kt">pointer</span><span class="p">);</span>
<span class="k">VAR</span> <span class="n">f</span><span class="p">:</span><span class="k">file</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="n">assign</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="n">name</span><span class="p">);</span>
  <span class="n">reset</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="m">1</span><span class="p">);</span>
  <span class="n">blockread</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="n">p</span><span class="p">^,</span><span class="n">filesize</span><span class="p">(</span><span class="n">f</span><span class="p">);</span>
  <span class="n">close</span> <span class="p">(</span><span class="n">f</span><span class="p">);</span>
<span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>In FPack.pas, we do the following:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">Function</span> <span class="n">LoadData</span> <span class="p">(</span><span class="n">num</span><span class="p">:</span><span class="kt">integer</span><span class="p">;</span> <span class="n">p</span><span class="p">:</span><span class="kt">pointer</span><span class="p">):</span><span class="kt">Boolean</span><span class="p">;</span>
<span class="k">VAR</span> <span class="n">f</span><span class="p">:</span><span class="k">file</span><span class="p">;</span>
<span class="k">BEGIN</span>
  <span class="k">If</span> <span class="n">pack</span> <span class="k">then</span> <span class="k">BEGIN</span>
    <span class="n">assign</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="n">paramstr</span><span class="p">(</span><span class="m">0</span><span class="p">));</span>
    <span class="n">reset</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="m">1</span><span class="p">);</span>
    <span class="n">seek</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="n">infopos</span><span class="p">[</span><span class="n">num</span><span class="p">]);</span>
    <span class="n">blockread</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span> <span class="n">p</span><span class="p">^,</span> <span class="n">infopos</span><span class="p">[</span><span class="n">num</span><span class="p">+</span><span class="m">1</span><span class="p">]-</span><span class="n">infopos</span><span class="p">[</span><span class="n">num</span><span class="p">]);</span>
    <span class="n">close</span> <span class="p">(</span><span class="n">f</span><span class="p">);</span>
  <span class="k">END</span> <span class="k">else</span> <span class="k">BEGIN</span>
    <span class="n">assign</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="n">infodat</span><span class="p">[</span><span class="n">num</span><span class="p">]);</span>
    <span class="n">reset</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span><span class="m">1</span><span class="p">);</span>
    <span class="n">blockread</span> <span class="p">(</span><span class="n">f</span><span class="p">,</span> <span class="n">p</span><span class="p">^,</span> <span class="n">filesize</span> <span class="p">(</span><span class="n">f</span><span class="p">));</span>
    <span class="n">close</span> <span class="p">(</span><span class="n">f</span><span class="p">);</span>
  <span class="k">END</span><span class="p">;</span>
<span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>As you can see, we just have two special cases depending on whether or not
the .exe file has been packed yet.</p>

<p><em>NOTE: After you have packed the file, you CAN NOT pklite it. You can
       however pklite the .exe_before you run pack.exe … in other
       words, you cannot use pklite to try pack your data files.</em></p>

<p>PACK.EXE does have a limitation … you can only pack 24 data files together.
If you would like it to do more, mail me … It should be easy to increase the
number.</p>

<p>In the sample program, FINAL.EXE is the same as temp.pas, except it has
its PCX embedded inside it. I ran pack2.exe, selected final.exe and
eye.pcx, hit “C”, and there it was. You will notice that eye.pcx is not
included in the directory … it is now part of the exe!</p>

<h2 id="in-closing">In closing</h2>

<p>Well, that’s about it for this trainer… next one (as I have mentioned
twice already ;) will be on assembler, with a flame routine thrown in.</p>

<p>This tut has been a bit of a departure from normal tuts … aside from the
PCX loading routines, the rest has been “non programming” oriented …
don’t worry, next week’s one will be back to normal.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="demo" /><summary type="html"><![CDATA[This trainer is about reading PCX files, file packing, and putting everything into one executable file.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/demoscene.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/demoscene.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Denthor/Asphyxia’s VGA trainers: Pixel morphing</title><link href="http://www.independent-software.com/denthor-asphyxia-vga-trainer-17-pixel-morphing.html" rel="alternate" type="text/html" title="Denthor/Asphyxia’s VGA trainers: Pixel morphing" /><published>2023-02-06T15:16:00+00:00</published><updated>2023-02-06T15:16:00+00:00</updated><id>http://www.independent-software.com/denthor-asphyxia-vga-trainer-17-pixel-morphing</id><content type="html" xml:base="http://www.independent-software.com/denthor-asphyxia-vga-trainer-17-pixel-morphing.html"><![CDATA[<p>This trainer is on a few demo effects (pixel morphs and static).</p>

<!--more-->

<div style="background:steelblue; color: white; border-top: solid 1px #333; border-bottom: solid 1px #333; padding-bottom: 32px; margin-bottom: 32px;">

  <pre style="background: none; text-align: center">
DENTHOR, coder for ...
_____   _____   ____   __   __  ___  ___ ___  ___  __   _____
/  _  \ /  ___&gt; |  _ \ |  |_|  | \  \/  / \  \/  / |  | /  _  \
|  _  | \___  \ |  __/ |   _   |  \    /   &gt;    &lt;  |  | |  _  |
\_/ \_/ &lt;_____/ |__|   |__| |__|   |__|   /__/\__\ |__| \_/ \_/
smith9@batis.bis.und.ac.za
The great South African Demo Team! Contact us for info/code exchange!  
</pre>

  <p style="text-align:center; font-weight: bold">Grant Smith, alias Denthor of Asphyxia, wrote up several articles on the 
creation of demo effects in the 90s. I reproduce them here, as they offer
so much insight into the demo scene of the time.
</p>

  <p style="text-align: center">
These articles apply some formatting to Denthor's original ASCII files, plus
a few typo fixes.
</p>

</div>

<h2 id="pixel-morphing">Pixel Morphing</h2>

<p>Have you ever lain down on your back in the grass and looked up at the
cloudy sky? If you have, you have probably seen the clouds move together
and create wonderful shapes… that cloud plus that cloud together make a
whale… a ship… a face etc.</p>

<p>We can’t quite outdo Mother Nature, but we can sure give it a shot. The
effect I am going to show you is where various pixels at different starting
points move together and create an overall picture.</p>

<p>The theory behind it is simple: each pixel has bits of data associated
with it, most important of which is as follows:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>This is my color
This is where I am
This is where I want to be.
</code></pre></div></div>

<p>The pixel, keeping its color, goes from where it is to where it wants to
be. Our main problem is <em>how</em> it moves from where it is to where it wants
to be. A obvious approach would be to say “If its destination is above it,
decrement its <code class="language-plaintext highlighter-rouge">y</code> value, if the destination is to the left, decrement its <code class="language-plaintext highlighter-rouge">x</code>
value and so on.”</p>

<p>This would be bad. The pixel would only ever move at set angles, as you can
see below:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>                Dest   O-----------------\
                                           \  &lt;--- Path
                                             \
                                               \
                                                O Source
</code></pre></div></div>

<p>Doesn’t look very nice, does it? The pixels would also take different times
to get to their destination, whereas we want them to reach their points at
the same time, i.e.:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>     Dest 1   O-------------------------------O Source 1
     Dest 2   O-----------------O Source 2
</code></pre></div></div>

<p>Pixels 1 and 2 must get to their destinations at the same time for the best
effect. The way this is done by defining the number of frames or “hops”
needed to get from source to destination. For example, we could tell pixel
one it is allowed 64 hops to get to its destination, and the same for
point 2, and they would both arrive at the same time, even though pixel 2
is closer.</p>

<p>The next question, it how do we move the pixels in a straight line? This is
easier than you think…</p>

<p>Let us assume that for each pixel, <code class="language-plaintext highlighter-rouge">x1,y1</code> is where it is, and <code class="language-plaintext highlighter-rouge">x2,y2</code> is where
it wants to be.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>   (x2-x1) = The distance on the X axis between the two points
   (y2-y1) = The distance on the Y axis between the two points
</code></pre></div></div>

<p>If we do the following:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  dx := (x2-x1)/64;
</code></pre></div></div>

<p>we come out with a value in <code class="language-plaintext highlighter-rouge">dx</code> which is very useful. If we added <code class="language-plaintext highlighter-rouge">dx</code> to <code class="language-plaintext highlighter-rouge">x1</code> 64
times, the result would be <code class="language-plaintext highlighter-rouge">x2</code>! Let us check…</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  dx = (x2-x1)/64
  dx*64 = x2-x1         { Multiply both sides by 64 }
  dx*64+x1 = x2         { Add x1 to both sides }
</code></pre></div></div>

<p>This is high school math stuff, and is pretty self explanatory. So what we
have is the x movement for every frame that the pixel has to undergo. We
find the y movement in the same manner.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  dy := (y2-y1)/64;
</code></pre></div></div>

<p>So our program is as follows:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code>  <span class="cm">{ Set x1,y1 and x2,y2 values }</span>
  <span class="n">dx</span><span class="p">:=</span> <span class="p">(</span><span class="n">x2</span><span class="p">-</span><span class="n">x1</span><span class="p">)/</span><span class="m">64</span><span class="p">;</span>
  <span class="n">dy</span><span class="p">:=</span> <span class="p">(</span><span class="n">y2</span><span class="p">-</span><span class="n">y1</span><span class="p">)/</span><span class="m">64</span><span class="p">;</span>

  <span class="k">for</span> <span class="n">loop1</span><span class="p">:=</span><span class="m">1</span> <span class="k">to</span> <span class="m">64</span> <span class="k">do</span> <span class="k">BEGIN</span>
    <span class="n">putpixel</span> <span class="p">(</span><span class="n">x1</span><span class="p">,</span><span class="n">y1</span><span class="p">)</span>
    <span class="n">wait</span><span class="p">;</span>
    <span class="n">clear</span> <span class="n">pixel</span> <span class="p">(</span><span class="n">x1</span><span class="p">,</span><span class="n">y1</span><span class="p">);</span>
    <span class="n">x1</span><span class="p">:=</span><span class="n">x1</span><span class="p">+</span><span class="n">dx</span><span class="p">;</span>
    <span class="n">y1</span><span class="p">:=</span><span class="n">y1</span><span class="p">+</span><span class="n">dy</span><span class="p">;</span>
  <span class="k">END</span><span class="p">;</span>
</code></pre></div></div>

<p>If there was a compiler that could use the above pseudocode, it would move
the pixel from x1,y1 to x2,y2 in 64 steps.</p>

<p>So, what we do is set up an array of many pixels with this information, and
move them all at once… voilá, we have pixel morphing! It is usually best
to use a bitmap which defines the color and destination of the pixels, then
randomly scatter them around the screen.</p>

<p>Why not use pixel morphing on a base object in 3d? It would be the work of
a moment to add in a Z axis to the above.</p>

<p>The sample program uses fixed point math in order to achieve high speeds,
but it is basically the above algorithm.</p>

<h2 id="static">Static</h2>

<p>A static screen was one of the first effects Asphyxia ever did. We never
actually released it because we couldn’t find anywhere it would fit. Maybe
you can.</p>

<p>The easiest way to get a screen of static is to tune your TV into an unused
station … you even get the cool noise effect too. Those people who build
TVs really know how to code ;-)</p>

<p>For us on a PC however, it is not as easy to generate a screen full of
static (unless you desperately need a new monitor)</p>

<p>What we do is this:</p>

<ul>
  <li>Set colors 1-16 to various shades of grey.</li>
  <li>Fill the screen up with random pixels between colors 1 and 16</li>
  <li>Rotate the palette of colors 1 to 16.</li>
</ul>

<p>That’s it! You have a screenful of static! To get two images in one static
screen, all you need to do is fade up/down the specific colors you are
using for static in one of the images.</p>

<p>A nice thing about a static screen is that it is just palette rotations
… you can do lots of things in the foreground at the same time (such as a
scroller).</p>

<h2 id="in-closing">In closing</h2>

<p>Well, that is about it … as I say, I will be doing more theory stuff in
future, as individual demo effects can be thought up if you know the base
stuff.</p>

<p>Note the putpixel in this GFX3.PAS unit … it is <em>very</em> fast .. but
remember, just calling a procedure eats clock ticks… so embed putpixels
in your code if you need them. Most of the time a putpixel is not needed
though.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="demo" /><summary type="html"><![CDATA[This trainer is on a few demo effects (pixel morphs and static).]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/demoscene.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/demoscene.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Denthor/Asphyxia’s VGA trainers: Plasmas</title><link href="http://www.independent-software.com/denthor-asphyxia-vga-trainer-15-plasma.html" rel="alternate" type="text/html" title="Denthor/Asphyxia’s VGA trainers: Plasmas" /><published>2023-02-06T15:06:00+00:00</published><updated>2023-02-06T15:06:00+00:00</updated><id>http://www.independent-software.com/denthor-asphyxia-vga-trainer-15-plasma</id><content type="html" xml:base="http://www.independent-software.com/denthor-asphyxia-vga-trainer-15-plasma.html"><![CDATA[<p>Plasmas are a great way to wow your friends by their weird shapes and forms.
I was at one stage going to write a game where the bad guy just had two
circular plasmas instead of eyes… I am sure you will find creative and
inventive new ways of doing and using plasmas.</p>

<!--more-->

<div style="background:steelblue; color: white; border-top: solid 1px #333; border-bottom: solid 1px #333; padding-bottom: 32px; margin-bottom: 32px;">

  <pre style="background: none; text-align: center">
DENTHOR, coder for ...
_____   _____   ____   __   __  ___  ___ ___  ___  __   _____
/  _  \ /  ___&gt; |  _ \ |  |_|  | \  \/  / \  \/  / |  | /  _  \
|  _  | \___  \ |  __/ |   _   |  \    /   &gt;    &lt;  |  | |  _  |
\_/ \_/ &lt;_____/ |__|   |__| |__|   |__|   /__/\__\ |__| \_/ \_/
smith9@batis.bis.und.ac.za
The great South African Demo Team! Contact us for info/code exchange!  
</pre>

  <p style="text-align:center; font-weight: bold">Grant Smith, alias Denthor of Asphyxia, wrote up several articles on the 
creation of demo effects in the 90s. I reproduce them here, as they offer
so much insight into the demo scene of the time.
</p>

  <p style="text-align: center">
These articles apply some formatting to Denthor's original ASCII files, plus
a few typo fixes.
</p>

</div>

<h2 id="how-do-plasmas-work">How do plasmas work?</h2>

<p>I will only cover one type of plasma here: a realtime plasma of course.
Other types of plasmas include a static picture with a pallette rotation.</p>

<p>When you get right down to it, this method of realtime plasmas is merely an
intersection of four COS waves. We get our color at a particular point by
saying:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>      col := costbl[one]+costbl[two]+costbl[three]+costbl[four];
</code></pre></div></div>

<p>The trick is getting the four indexes of that cos table array to create
something that looks nice. This is how we organize it: have two of them
being indexes for vertical movement and two of them being indexes for
horizontal movement.</p>

<p>This means that by changing these values we can move along the plasma. To
draw an individual screen, we pass the values of the four to another four
so that we do not disturb the original values. For every pixel across, we
add values to the first two indexes, then display the next pixel. For
every row down, we add values to the second two indexes. Sound complex
enough? Good, because that what we want, a complex shape on the screen.</p>

<p>By altering the original four values, we can get all sorts of cool movement
and cycling of the plasma. The reason we use a cos table is as follows:
a cos table has a nice curve in the value of the numbers… when you
put two or more together, it is possible to get circular pictures…
circles are hard to do on a computer, so this makes it a lot easier…</p>

<p>Okay, now you can have a look at the source file, all I do is put the above
into practice. I did add one or two things though…</p>

<p>Background: This is just a large array, with the values in the array being
added to the plasma at that pixel.</p>

<p>Psychedelic: This cycles through about 7000 colors instead of just rotating
through the base 256.</p>

<h2 id="clever-fading">Clever fading</h2>

<p>You will notice when the sample program fades in and out that the colors
all reach their destination at the same time … in other words, they don’t
all increment by one until they hit the right color then stop. When done
in that way the fading does not look as professional.</p>

<p>Here is how we do a step-crossfade:</p>

<p>Each r,g,b value can be between 0 and 64. Have the palette we want to get
to in <code class="language-plaintext highlighter-rouge">bob</code> and the temporary pallette in <code class="language-plaintext highlighter-rouge">bob2</code>. For each step, from 0 to 63
do the following:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code>     <span class="n">bob2</span><span class="p">[</span><span class="n">loop1</span><span class="p">].</span><span class="n">r</span><span class="p">:=</span><span class="n">bob</span><span class="p">[</span><span class="n">loop1</span><span class="p">].</span><span class="n">r</span><span class="p">*</span><span class="n">step</span><span class="p">/</span><span class="m">64</span><span class="p">;</span>
</code></pre></div></div>

<p>That means if we are halfway through the crossfade (step=32) and the red
value is meant to get to 16, our equation looks like this:</p>

<div class="language-pascal highlighter-rouge"><div class="highlight"><pre class="highlight"><code>    <span class="n">r</span><span class="p">:=</span><span class="m">16</span><span class="p">*</span><span class="m">32</span><span class="p">/</span><span class="m">64</span>
     <span class="n">r</span><span class="p">=</span><span class="m">8</span>
</code></pre></div></div>

<p>Which is half of the way to where it wants to be. This means all colors will
fade in/out with the same ratios… and look nicer.</p>

<h2 id="rotating-the-pallette">Rotating the pallette</h2>

<p>I have done this one before, I think. Here it is:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>move color 0 into temp

move color 1 into color 0
move color 2 into color 1
move color 3 into color 2
and so on till color 255

move temp into color 255

</code></pre></div></div>

<p>And your palette is rotating. Easy huh? Recheck <a href="/denthor-asphyxia-vga-trainer-2-palette.html">Part 2</a> for more info on
palette rotation.</p>

<h2 id="in-closing">In closing</h2>

<p>The tutorial was a bit short this time, but that is mostly because the
sample file is self-explanatory. The file can however be speeded up, and
of course you can add certain things which will totally change the look
of the plasma.</p>]]></content><author><name>Alexander van Oostenrijk</name></author><category term="demo" /><summary type="html"><![CDATA[Plasmas are a great way to wow your friends by their weird shapes and forms. I was at one stage going to write a game where the bad guy just had two circular plasmas instead of eyes… I am sure you will find creative and inventive new ways of doing and using plasmas.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="http://www.independent-software.com/assets/svg/demoscene.svg" /><media:content medium="image" url="http://www.independent-software.com/assets/svg/demoscene.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>